
KajoData / Career & business
Data cleaning: improve data without deleting its meaning
I follow a raw table through cleaning and show when to remove a record, preserve a missing value or investigate an unusual amount before publishing a report.
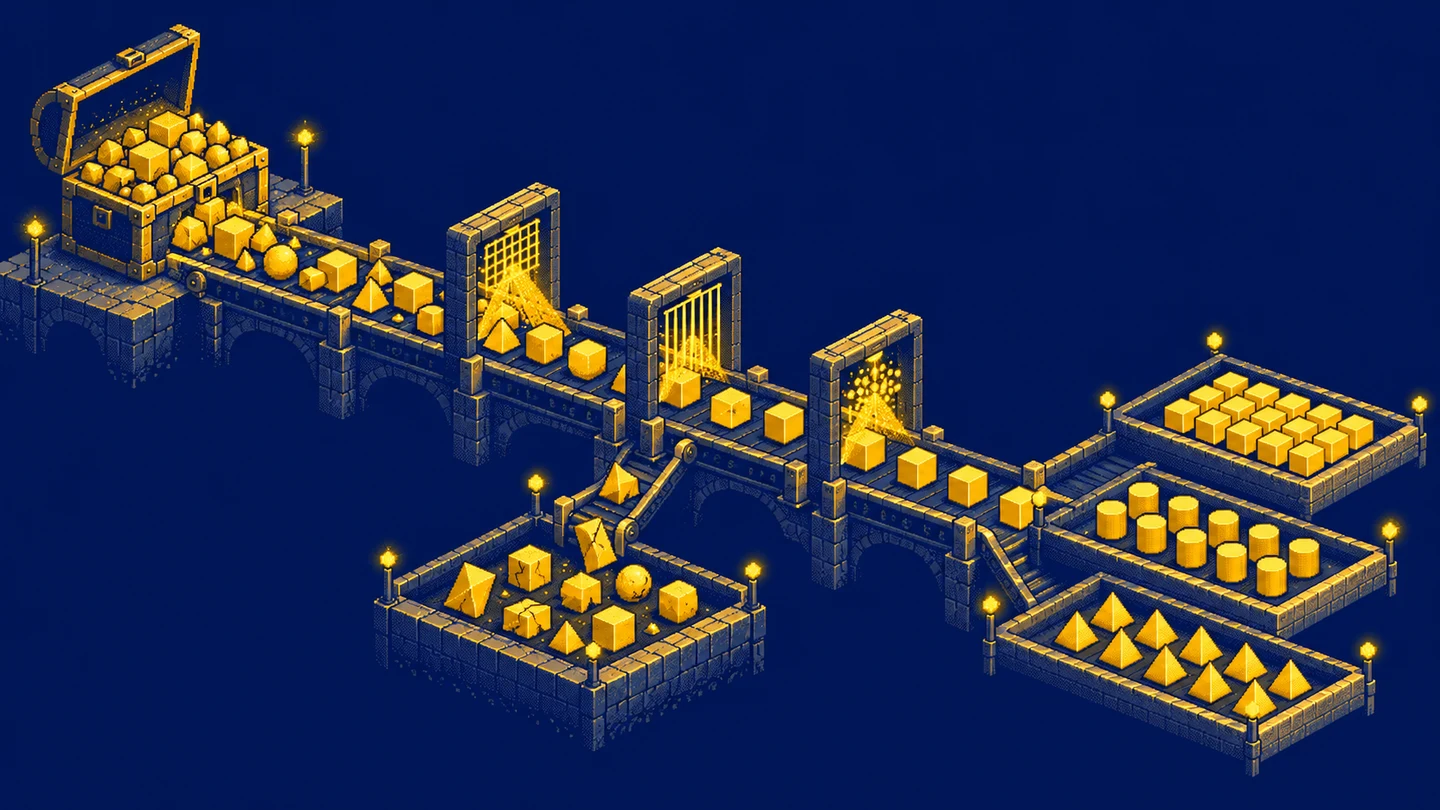
A chart can look excellent while counting the same order twice. When I receive a new dataset, I therefore start with records, missing values and column meanings. Data cleaning includes technical operations and decisions about what can legitimately change. A “remove duplicates” button does not know how your company defines an order, even if it can execute the operation instantly.
I would not assign a universal percentage of an analyst’s working time to cleaning. It depends on the source, process and task. I prefer to show the decisions needed before a result reaches its reader. This guide uses small synthetic data and arithmetic you can follow without running a program. The purpose is to make every change explainable rather than merely produce a table that looks tidier.
Define the goal and preserve the input
Suppose you are reporting order value by city. Before changing a cell, record the date range, export version and amount definition. Does the amount include tax, returns and cancellations? Does one row represent an order, an order line or a status-change event? Until those questions are answered, you cannot decide which repeated identifiers indicate an error.
I work through transformations from preserved input to output so the result can be reproduced and row-count changes can be located. A manual correction in the only copy makes that explanation difficult. Preserving input does not mean publishing it or copying it outside the agreed working location. It means retaining an appropriate reference against which the transformation can be explained.
Initially, I record row count, unique-key count, date coverage and a value total where units are comparable. These are reference points. Every operation need not preserve the total, but a changed total needs a reason. If trimming whitespace somehow reduces revenue, I want to know what else happened in that step before building a visualization on the result.
Profiling reveals places to investigate
Inspect column types, missingness, category values and suspicious ranges. Power Query’s Column quality, Column distribution and Column profile help with this. Microsoft’s documentation notes that profiling defaults to the first 1,000 rows and can be switched to the entire dataset. A clean-looking sample cannot establish the quality of records outside that sample.
Treat the profile as a collection of leads. More city categories than expected might reflect spaces, spelling differences or a genuinely wider sales area. A negative amount might represent a return, correction or error. Numeric type alone does not establish business validity. I need a rule and an understanding of how the source creates records before deciding whether to change them.
Start with fields that affect the answer. If the report groups by city and sums amounts, those columns and the key deserve particular attention. A complete audit of every field can be a separate task. Defining the scope lets you describe honestly what was checked and what this particular report still does not establish about the wider dataset.
Identify duplicates through keys and meaning
Here is a synthetic export in which one row is supposed to represent an entire order:
| Order | City | Amount |
|---|---|---|
| A | Warsaw | 100 |
| A | Warsaw | 100 |
| B | warsaw | missing |
| C | Krakow | 20 |
| D | Krakow | 900 |
Assume the source owner confirms that A was sent twice by mistake. Removing one copy is justified. The sum of known amounts falls from 1,120 to 1,020, and row count falls from five to four. The difference of 100 has a specific cause visible in the records. It is not an unexplained side effect of “making the data clean.”
If the rows represented order lines, both A records might be legitimate and the key might need a line number. If they represented successive order states, selecting the current state would need a separate rule. I would not choose the first record without a defined ordering, nor assume that taking the latest timestamp resolves every type of historical data.
In pandas, drop_duplicates lets you select comparison columns with subset and decide how to retain repetitions with keep; the index is ignored. These controls are described in the method documentation. The method executes your rule. It does not determine which combination of columns forms a valid business key or which record the report should retain.
Missingness preserves information
Order B has an unknown amount. Inserting zero would make the table appear complete while asserting that this order had no value. We do not know that. For this example, I report a known total of 1,020, four orders and one missing amount. I do not describe the total as complete revenue for all four orders, because the source does not support that claim.
The consequence becomes clearer with averages. The three known amounts after deduplication are 100, 20 and 900, giving a mean of 340. Replacing the missing value with zero and dividing by four gives 255. The arithmetic is simple in both cases; the disagreement concerns an assumption introduced into the data. The reader should see that assumption rather than receive an apparently definitive average.
Distinguish unknown values, fields that do not apply, pending updates and integration failures where possible. The pandas missing-data guide describes representations and operations that depend on data type. An empty string, zero and a missing-value marker are not interchangeable. Imputation needs justification and a way to identify which values were estimated rather than observed in the original source.
Format, dictionaries and units require separate decisions
“Warsaw” and “warsaw” can map to one label if that is the agreed rule. The number of categories changes while amounts remain unchanged. Ambiguous place names need a dictionary and identifier rather than just a case conversion. A short abbreviation can refer to different places, so expanding it automatically requires more evidence than a resemblance to a familiar label.
Identifiers often need to remain text. A code with a leading zero may lose meaning when converted to a number. Conversely, an amount stored as text needs its separators interpreted correctly. The string 1,234 can mean different things under different regional settings. Establish the source format first, convert accordingly, and inspect conversion errors separately instead of quietly dropping unsuccessful records.
Handle dates, currencies and measurement units with the same care. Similar cell appearance does not guarantee the same type or meaning. Currency conversion needs a rate, date and conversion rule; renaming a column is insufficient. If you cannot support the conversion, keep values separated by unit rather than adding them into a combined total that looks precise but has no coherent interpretation.
Customer attributes do not automatically make a table wrong
It is easy to confuse cleaning with a requirement to normalize every table. A customer name beside an order does not by itself prove a design error. It may be a deliberate analytical export, a historical snapshot or part of a reporting model. Establish the purpose and update rules before restructuring data solely because some descriptive attributes appear more than once.
Analytical models use fact and dimension tables, and the appropriate structure depends on analysis requirements. Microsoft’s star-schema guidance provides this context for Power BI. Standardizing category labels, scaling numerical features and relational normalization are different operations. Naming them accurately helps the reader understand what changed and prevents a simple cleanup instruction from turning into an unsupported architectural prescription.
I first check whether attributes describe the intended time and whether a join preserves the expected multiplicity. If a customer table contains several versions of a person, joining on identifier alone can repeat orders. A temporal rule or a suitable version selection may be needed. Moving names into a separate table does not, by itself, ensure that the resulting analysis is correct.
Investigate an unusual amount before deleting it
The amount of 900 is much larger than 100 and 20. That is a reason to investigate, rather than an automatic reason to delete. It might be a large purchase, a different unit or a mistake. If it is valid, removing it understates observed sales. If it is erroneous, correction needs evidence and a record of the decision that changed the source-derived result.
NIST distinguishes identifying outliers from deciding how to handle them. A confirmed error can be corrected or excluded; an unexplained unusual observation may require a different analytical approach. “Statisticians never remove outliers” is too broad. Removing everything beyond an arbitrary threshold because the chart then looks nicer is equally difficult to defend as a general cleaning rule.
When uncertainty remains, show its scale and effect. You can present the analysis with the record and a clearly labeled alternative excluding it. The reader sees the consequences, and the source owner receives a concrete question to resolve. A visible “needs investigation” status may provide more useful information than a silent edit that makes the report appear comfortably complete.
Reconcile again after combining sources
Cleaning one table does not finish the job. Adding a city or customer dictionary can repeat or lose records. Check row counts, unmatched keys and any measure total expected to remain unchanged before and after the join. If a dictionary should provide one match per key, several rows for that key need explanation before the table is used in a report.
In pandas merge, validate checks expected relationship cardinality, while indicator helps distinguish match origins. The merge documentation also warns that null join keys can match each other, unlike typical SQL behavior. Do not transfer one tool’s rules to another without checking. A familiar operation name can hide a materially different treatment of missing identifiers.
For our example, I expect four orders and a known amount total of 1,020 after city labels are assigned. If five rows appear, inspect the dictionary. If B disappears, check whether its missing amount or an unmatched key accidentally caused the entire order to be discarded. These are different problems and need different correction rules rather than a broad instruction to remove incomplete rows.
Record rules and publication conditions
A useful transformation note states what changed and why: one confirmed copy of A was removed, a city label was standardized, B’s missing amount was preserved, and D was sent for investigation. Record how many rows each operation affected. This makes the next export comparable with the previous one without requiring somebody to reconstruct every decision from memory or interpret an unexplained total.
Before publication, agree whether an unresolved issue blocks the whole report, one measure or a particular segment. A missing amount need not prevent reporting order count. It may prevent a claim about complete revenue. Making that distinction lets you deliver a useful result with an honest limitation instead of pretending all columns have reached ideal quality or withholding unrelated information unnecessarily.
Rules can then be automated. Repeated checks, conversions and alerts for new exceptions are good candidates. A rule still needs review when the source process changes. A new status, unit or export version may invalidate an earlier assumption even while the transformation continues to run successfully. Reproducible execution and an up-to-date meaning are separate requirements for reliable reporting.
Operation order can hide problems
Two identifiers may differ only by a trailing space. Checking duplicates before a justified cleanup can miss them; stripping differences without a valid rule can merge distinct identifiers. Preserve a way to compare original and resulting keys in the agreed working environment. A lower distinct-key count may reflect either an intended reconciliation or an accidental collision, so the count alone cannot tell you which occurred.
Filtering can hide missingness too. If every row without an amount is removed before profiling, the remaining table will appear complete. Count exclusions and their reasons against the input, rather than letting the final table define its own quality denominator. Likewise, keep the pre-join reference total. Two successive outputs can agree while both contain the same unintended multiplication.
Distinguish a reporting workaround from a source repair
A city dictionary may make this report usable, but recurring spelling problems also deserve a conversation about data entry or export rules. Otherwise, every analysis must recreate the workaround and different people may choose different mappings. State what happens to existing records now and what could prevent new errors in the source process.
Give the source owner a small example and a precise question. “The city data are messy” is difficult to act on. “This identifier has two conflicting labels; which is correct and from what date?” can receive a useful answer. That conversation is concrete analytical work because the transformation would otherwise be based on a guess. A successful workaround should not quietly become evidence that the source problem has disappeared.
Exercise: defend every change
Use the example table to make two lists: confirmed operations and questions requiring the source owner’s answer. Explain why one copy of A can be removed while D cannot immediately be deleted. State exactly what the known total of 1,020 describes and why you would not call it complete revenue for every order represented after deduplication.
Then change the assumption so one row represents an order line. Which earlier decisions lose their justification? The exercise connects data structure with cleaning rules. The goal is to explain why an operation preserves or changes information required for the answer, rather than memorize five buttons and apply them to every dataset that looks untidy.
For a broader workflow, read the guide to data cleaning stages and the Power Query introduction. The habit I would keep from this article is to compare the result with its source after each meaningful change and state the reason for any difference. That gives the next person a result whose numbers can be traced and defended.
Key takeaways
Should I delete every repeated identifier?
First define the row and full key. Several lines of one order or a change history may be a valid structure rather than duplicate records.
Can I always replace missing numbers with zero?
Zero has a specific meaning. A missing value may represent an unknown amount, an integration problem or a field that does not apply. Replacement needs a rule appropriate to the analysis.
Should outliers be removed before reporting?
Investigate the cause first. A confirmed error can be corrected or excluded under an explicit rule, while an unusual valid event may be the most useful information in the dataset.
AI was used in an automated way while working on this article. If you want to learn how to do it too, check out this project.
