
KajoData / Career & business
Data problems in companies: definitions, collaboration and ownership
Three reports show different order counts. I use one example to explain how to investigate the difference, agree on a definition and decide who will fix it.
Three reports arrive at a meeting. Each shows a different number of orders. Within minutes, the discussion turns to technology: perhaps we need a new dashboard, another platform or some AI. I would begin with a less exciting question. What exactly did each report count?
Technology deserves attention. A broken import or an incorrect join can absolutely damage a result. Alongside those technical issues, however, I would look at four organisational problems: inconsistent definitions, competition between teams, tool chaos and unclear ownership. Replacing a reporting application will not, by itself, decide which orders the business considers completed.
I will work through one situation and show how I would approach it. All numbers and scenarios in this article are synthetic. You can use them as an exercise or as a starting point for a conversation about your own reporting. They do not describe a particular client or implementation.
A Single Source of Truth starts with the meaning of a number
A Single Source of Truth sounds like a promise of peace. Put everything in one place and the arguments should finally stop. Yet one database can still support three queries answering three different questions. A shared location does not define a column called “orders”.
My starting point would be an agreed model for a particular use. We know where its data comes from, what its fields mean, who approves the definition and how to report a problem. The store, payment and warehouse systems can remain separate. What matters is documenting their relationships and choosing which event each metric uses.
I would normally distinguish the data received from sources, the preparation process and the layer used for reporting. That is a useful way to organise the work, rather than a compulsory architecture for every company. A small team may start with a documented query and a result table. A larger organisation has more dependencies, versions and changes to coordinate.
People must also be able to challenge the result. An agreed model can contain a mistake. Saying that a report is official does not resolve a discrepancy. I want to see a record, its expected treatment and a difference that someone else can reproduce. Trust improves when corrections follow a predictable route and users hear about changes.
Sometimes the shared model does not yet support a team’s needs. A temporary analysis alongside it may be reasonable. I would label its scope, author, limitations and review date. The difficulty begins when a temporary spreadsheet quietly becomes a recurring report. Months later, nobody remembers why it was created or how it differs from the shared version.
A worked example: why the reports show 1000, 940 and 910
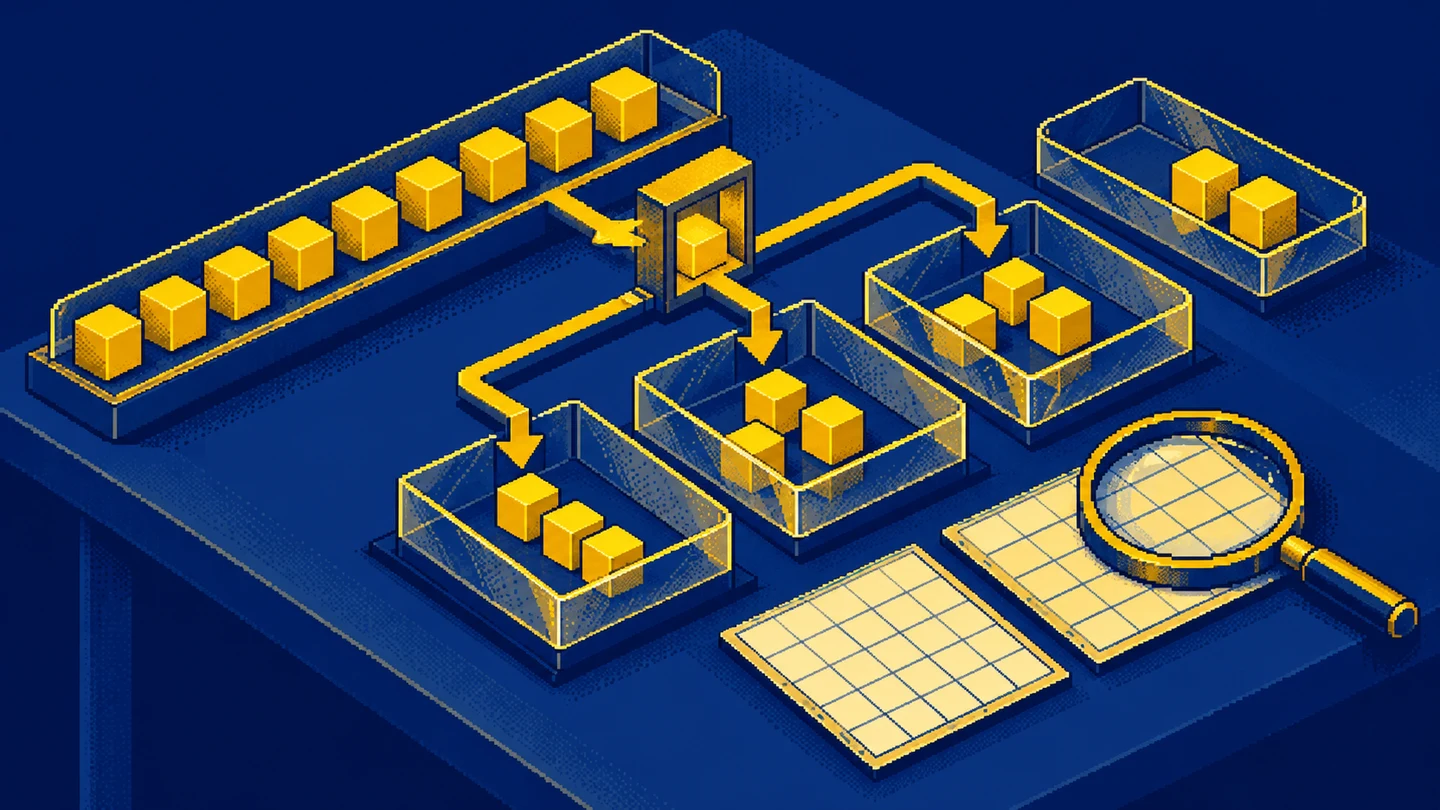
Suppose a store recorded 1000 orders created in September. Every order has a unique identifier, and test records have been excluded. Of that September group, 940 orders were paid by the end of September. Among those paid orders, 30 were cancelled before shipment, also before the end of September. In this example, cancelled orders are a subset of paid orders. We interpret dates in the Europe/Warsaw time zone.
| Report | What it counts within the same September order cohort | Result |
|---|---|---|
| Placed | Unique orders created in September | 1000 |
| Paid | Orders paid by the end of September | 940 |
| Paid excluding cancellations | Paid orders less those cancelled by the end of September | 910 |
The first difference, 60, represents orders in the cohort that had not been paid by the specified cutoff. The next difference, 30, comes from excluding cancellations. The final result is 940 minus 30. All three numbers can be correct under these definitions. Labelling all of them simply “orders” gives the reader no way to understand why they differ.
These are order counts. We are not calculating revenue, profit or the number of shipments. The remaining 910 orders have not necessarily been dispatched. An order can also generate several parcels, so replacing an order identifier with a parcel identifier would change the unit of analysis. I would settle those details before designing a chart.
Now suppose the first report shows 1005 after a refresh on 2 October. I would not immediately conclude that September had five additional orders. We need to inspect identifiers, event dates and arrival times. Late data, a changed filter or duplicated rows after a join are all possible explanations. Each calls for a different check.
To reconstruct the position at the end of September, we need event history or a preserved snapshot. Today’s order status does not necessarily tell us its status a month ago. If that history is unavailable, I would state the limitation. Filtering by creation date alone cannot reconstruct the earlier state of payments and cancellations.
Write a metric specification someone can actually use
For the shared report, I would prepare a short metric specification. A new team member should be able to understand the result and reproduce a small sample from it. A document containing only a name and a general formula leaves too much room for guesswork, especially when two departments attach different meanings to the same name.
Our full metric name could be “September orders paid by the end of September, excluding orders cancelled by that cutoff”. I would specify the unit as a unique order identifier. The creation window starts at the beginning of 1 September and ends at the beginning of 1 October, excluding that second boundary. The time zone, payment conditions, cancellation rules and test-record exclusion belong in the same specification.
Operational details matter too: the source, the location of the definition in code, the refresh time, known delays and the owner. I would add a rule version and its effective date. If we change the definition in November, we must decide whether to recalculate earlier periods. Otherwise, a month-to-month comparison may look like a business change when only the counting rule changed.
Finally, I would include boundary cases. An order created on the last day of the month. A payment received in the next month. A cancellation before the cutoff and another after it. Each case should have an expected inclusion result. A handful of concrete examples can expose more misunderstanding than another meeting about whether the definition is obvious.
The specification also needs a home that people can find from the report. I would link the report to the definition and the definition to its implementation. If an analyst has to search through old chat messages to discover the active rule, the documentation is not yet doing its job. Keeping those connections current should belong to someone’s regular work.
Collaborate around the discrepancy
When two teams bring different totals, it is tempting to question each other’s competence. I would start by comparing scope. Ask both sides for the refresh time, filter conditions and a small sample of identifiers found on only one side. That changes the conversation from defending a report to investigating a difference together.
The discussion should distinguish two situations. In the first, the reports answer different questions and need clearer names and descriptions of their intended use. In the second, they are meant to answer the same question, but their implementations disagree. That requires an error investigation. Making totals match by arbitrarily removing records would simply hide the problem until the next refresh.
My investigation note might say: “The difference contains 30 identifiers. Each has a cancellation before the period cutoff. Report A excludes them; report B includes them. The metric owner will confirm which definition applies to this use.” The note contains evidence, a decision to make and a next step. Someone can understand it without reconstructing an hour-long discussion.
Managers have a practical responsibility here. They need to set priorities and allow time for a joint investigation, particularly when a metric affects how teams are assessed. I would not expect an analyst to resolve conflicting organisational objectives alone. The analyst can show the consequences of different definitions. Choosing the objective belongs to the people responsible for that business area.
There is also a useful habit at the individual level: describe what you observed before explaining what you think caused it. “These identifiers are absent” is more actionable than “your pipeline is unreliable”. The first statement gives the other team something to check. The second makes them defend an entire system before anyone has examined the evidence.
Tool chaos and the cost of another solution
A new tool may solve a real limitation: insufficient performance, an unavailable source connection or an expensive process to maintain. I would not reject a change merely because the existing system is familiar. I would name the limitation and test whether the proposed solution removes it. Product demonstrations tend to show the happy path. Monday morning’s import may be less cooperative.
Before choosing anything, I would map the report’s flow. Where is the data collected? Where is it transformed? Where does the counting rule live? Who consumes the result? If the same rule exists independently in a spreadsheet, a query and a dashboard, another platform may add a fourth version. In that situation, I would first clarify responsibility for the rule.
The comparison should include integration maintenance, training, monitoring, backup coverage and the ability to leave the tool. A useful trial should encounter an invalid record, late data, a rerun and a schema change. Those cases reveal work that remains after the first attractive chart. I explore selection criteria further in the comparison of Tableau and Power BI.
A pilot needs a user, a deadline and a completion criterion. I would also identify who decides whether to maintain or retire the result. Otherwise, the company accumulates experiments that nobody develops and everybody is afraid to touch. Each process consumes attention when sources change and makes it harder to establish where a reported number originated.
This does not mean every exploratory notebook needs a committee. I would apply more structure when an experiment becomes something other people depend on. The transition into recurring use is the point to agree on support, ownership and limitations. The level of process should reflect the consequence of failure, rather than the enthusiasm of the person proposing the tool.
Data ownership requires authority and time
“The data team owns the data” is too broad to resolve an incident. I want to know who decides what a metric means, who maintains its definition and who repairs its processing. Those responsibilities do not always require three different people. In a small company they may overlap, but the decision boundaries should remain explicit.
Tools also distinguish responsibilities. Microsoft Purview documents separate roles for areas including data products, governance domains and stewardship. That is a particular product’s model, rather than a universal organisation chart. For our example, I would use the following simpler division of work.
| Responsibility | What needs to happen for the order report |
|---|---|
| Business owner | Approves the metric’s meaning, intended use and repair priority |
| Definition and quality steward | Maintains the description, investigates discrepancies and coordinates clarification |
| Technical team | Operates processing, tests and monitoring, and implements agreed changes |
| Report user | Checks that the result supports the intended decision and reports problems with context |
For each responsibility, I would name a person or team, a backup and a reporting channel. A table without people or available time can look impressive in documentation. During an incident, you will still discover that the right person is on holiday or that the task was never part of anyone’s agreed workload.
The owner does not need to repair every query personally. They should be able to decide that a problem requires action and establish its urgency. Without that authority, ownership becomes a job of forwarding messages between teams. There must also be an escalation route when the fix belongs in a source system outside the analytics team’s direct control.
I would explicitly recognise maintenance work. Updating definitions, checking tests after a source change and preparing backup coverage rarely look spectacular. Without them, the same issue returns in the following month. Planning should reserve time for these activities instead of assuming that they will fit between urgent requests for new reports.
Quality must suit the intended use
The Government Data Quality Framework treats quality in terms of fitness for purpose. Data adequate for approximate planning may be inadequate for a specific reconciliation. I would establish the intended decision first, then agree on requirements and acceptable limitations.
It helps to distinguish the dimensions of data quality: completeness, uniqueness, consistency, timeliness, validity and accuracy. A complete table can contain incorrect values. A date in the correct format can still describe the wrong day. One passing check cannot represent every aspect of quality.
For our store, I would start with operational questions. Did the whole expected batch arrive? Is the order identifier unique in the orders table? Are the events needed to reconstruct status available? Does the report display its last successful data refresh? A failed check should lead to a defined action, such as marking the report incomplete and notifying the responsible person.
I would not apply one tolerance to every problem. A duplicated key in a table intended to contain one row per order presents a different risk from a short delay in an approximate planning report. I would agree on thresholds with users based on the consequences of error. If missing data could change their decision, a visible incompleteness notice is more useful than a misleadingly precise total.
What to do when the report stops reconciling
First, I would preserve the context: the definition version, refresh time and scope of the issue. Then I would identify which decisions depend on the result. If the problem affects one segment, the notice should say so. If the scope is still unknown, I would avoid declaring the rest of the report correct on intuition alone.
Next, I would trace a small sample from source to final count. Check record arrival, keys, filters, joins and aggregation. Understanding SQL join types helps when records are being multiplied. The correction should address the cause; manually adjusting the final cell will not repair the next run.
Before closing the issue, I would rerun the cases that exposed it and assess the effect on earlier periods. Users should hear what changed, which results need replacing and what limitations remain. If the investigation takes longer, give them a time for the next update. Silence encourages people to create their own competing versions of the report.
A small repair plan and an exercise
I would begin with one report that repeatedly causes disagreement and supports a concrete decision. The first conversation should establish the user, the meaning of the result and its sources. Next, I would work with a technical colleague to reproduce one discrepancy using identifiers. With that evidence available, we can agree on a correction and assign responsibilities.
After implementation, I would observe several subsequent refreshes. Does the discrepancy return? Can the user find the definition and report a problem? Can a backup person inspect the process without its original author? Those questions help assess whether the working arrangement improved. Creating a document or purchasing a tool does not demonstrate that by itself.
For your own exercise, choose a report you know or return to the synthetic store. Write five sentences explaining what you count, which group it covers, the relevant time window, the exclusions and the decision it supports. Ask someone else to describe the calculation from those sentences. Every point where they must guess is a candidate for clarification.
Finally, change one condition. Of the 60 unpaid September orders, 10 are paid on 2 October and remain uncancelled. If the observation cutoff stays at the end of September, the totals remain 1000, 940 and 910. Observing the same cohort through the end of 2 October gives 1000, 950 and 920, provided nothing else changes. Can you now name both reports so that a reader understands the difference? That is where I would start improving the company’s data.
Key takeaways
Does a Single Source of Truth require one database?
You can have several source systems. For a particular metric, you need an agreed definition, an identified model, traceable data and a way to request changes or report errors. Centralisation alone does not provide those things.
Do different report totals always indicate an error?
No. Reports may use different events, filters, dates or refresh times. Compare their definitions and record identifiers first. The same scope and observation time should produce a consistent result.
Who should own data in a company?
Identify who decides what the data means, who maintains definitions and quality, and who operates the processing. In a small company these responsibilities can overlap, but they still need time, authority and backup coverage.
