
KajoData / Python
Python variables, data types and operators: a practical starting point
Two names can share one list, and the text False can behave like true. I explain Python basics through a small data task, including the quiet mistakes that change your results.
When I start working with Python, I want to get to something useful quickly. Load some data, calculate a result, check an idea. A complete list of operators feels a little like the manual for a remote control. I understand why it exists. I am still looking for the button that does the job.
The trouble starts when the code runs successfully while answering a different question. A number turns out to be text. Editing a copy changes the original. A missing value disappears together with a perfectly valid zero. I therefore teach these basics through analytical decisions: what I am storing, how I can change it, and what would count as a correct result.
The examples use synthetic data and Python 3.14.7, without external libraries. Each code block can run independently. Comments show the expected output so you can compare it with your own result. At the end I combine the pieces into a small order summary. You do not need pandas or database experience to follow it.
A variable is a name referring to an object
I begin with assignment. The name on the left lets me refer to the object produced by the expression on the right. The equals sign does not ask whether two things are equal here. It tells Python which result this name should refer to from now on.
orders_count = 12
previous_count = orders_count
orders_count = orders_count + 3
print(orders_count, previous_count)  # 15 12
After the second assignment, both names refer to the integer twelve. I then calculate a new integer and assign it to orders_count. The name previous_count still refers to the earlier object. This explains why saving a previous value works here, while a similar approach with a list can be surprising.
I do not have to declare the name’s type beforehand. I could later assign a string to it, but that would usually make my analysis harder to follow. If orders_count sometimes means an order count and sometimes an error message, every later operation needs to account for both possibilities. I prefer separate names with stable meanings.
In a notebook, I also watch execution order. A result may depend on an assignment I ran twenty minutes earlier. Before I consider an analysis reproducible, I restart the interpreter and run everything from the beginning. Seeing a table in the final cell tells me very little about whether someone else can recreate it.
A useful name includes the unit
I use lowercase words separated by underscores, such as delivery_days or price_cents. The name immediately tells me what the number represents. When two columns both contain a hundred, the unit matters more than an elegant abbreviation. A hundred days and a hundred cents support very different decisions.
Python distinguishes uppercase and lowercase letters, so count and Count are different names. An identifier cannot start with a digit or be a reserved keyword such as for. Certain Unicode characters, including Polish letters, are also allowed. The identifier documentation gives the precise rules.
For team projects, I usually choose English names using ASCII characters. That is a collaboration convention, rather than a language restriction. I also avoid naming variables list, str or sum. Those assignments can be legal, but they hide built-in tools I may want to use a few lines later.
When reading unfamiliar code, I turn names into questions. Does total include cancelled orders? Is rate a fraction or a percentage? If I have to guess, I improve the name or add a short comment explaining the business meaning. A comment saying “add three” next to an addition of three will not resolve that uncertainty.
Choose a type according to what the data means
I use int for a count, float for a measurement, str for a product name, and bool for a simple true-or-false condition. Types determine which operations make sense. Two strings can be concatenated and two numbers can be added. The same plus sign does not promise the same meaning.
print(12 + 3)             # 15
print("12" + "3")         # 123
print(type(12).__name__)  # int
print(type("12").__name__)  # str
print(2 + 3j)            # (2+3j)
Python also supports complex numbers through complex. I rarely need them in an ordinary sales report, but numbers come in more varieties than whole numbers and numbers with a decimal point. I do not choose a type solely from how a spreadsheet cell looks on screen.
I keep the identifier "0012" as text when the leading zeros belong to a product code. Converting it into an integer could destroy information required to join datasets. A phone number also contains digits, but adding two phone numbers does not produce a useful analytical result.
At the beginning of an analysis, I inspect several values and their types. Then I look for less convenient cases: an empty field, an unusually long identifier, a negative amount. Five tidy records shown on screen do not prove that the rest of the file follows the same structure. This matters especially when someone has prepared the file by hand.
Conversion needs a policy for failures
Text from a form or file often needs to become a number. I convert it explicitly after deciding what format I accept. Calling a conversion function cannot decide for me whether a comma is a decimal separator or a thousands separator.
print(int(" 12 "))      # 12
print(float("12.5"))    # 12.5
print(int(12.9))        # 12
try:
    int("12.5")
except ValueError:
    print("invalid integer")  # invalid integer
try:
    "12" + 3
except TypeError:
    print("incompatible types")  # incompatible types
Truncating a fractional part with int can conceal a data problem. If an order count is twelve and a half, I first investigate the field’s definition. Automatically turning it into twelve would create something that looks valid. For negative values, int also truncates towards zero, which differs from rounding down.
In a real import, I record which row failed conversion. I do not replace every failure with zero because that zero will later participate in averages and totals. Depending on the task, I stop processing or set problematic records aside for investigation. This is a decision about the quality of the analysis, as well as exception handling.
The final exercise deliberately accepts a narrow input format: whole numbers written as text and explicit missing values. That makes its boundaries understandable. A short example should not pretend to be a universal reader for every export from every system.
None separates missing information from a valid zero
In this article, None represents an unknown value. Zero represents a known value equal to zero. That distinction affects the denominator of an average. If two orders have values of a hundred and zero, their average is fifty. If the second amount is unknown, treating it as zero introduces an additional assumption.
amount = 0
missing = None
print(amount is None)   # False
print(missing is None)  # True
print(bool(amount), bool(missing), bool(""))  # False False False
print(bool("False"), bool("0"))              # True True
A truth-value condition is convenient, but it groups different situations together. An empty list, empty string, zero and None are false. The nonempty string "False" is true. Python checks the string’s truth value rather than interpreting the everyday meaning of the word. The built-in types documentation explains these rules.
When I receive a flag as text, I define the permitted values and map them explicitly. I do not blindly pass the field through bool. For missing values, I use is None, preserving legitimate zeros. For empty strings, I separately decide whether emptiness means missing information or a valid answer.
Lists, tuples, dictionaries and sets serve different purposes
A list stores an ordered sequence of elements. A dictionary associates keys with values, making it useful for a small record. A tuple is a sequence whose elements I cannot replace after creation. A set helps with membership checks and removing repetitions, but I do not treat it as an ordered report.
amounts = [100, 0, 50]
record = {"order_id": "A01", "amount": 100}
point = (10, 20)
statuses = {"paid", "cancelled", "paid"}
print(amounts[0], record["amount"], point[1])  # 100 100 20
print(sorted(statuses))  # ['cancelled', 'paid']
print(list(range(1, 4)))  # [1, 2, 3]
The first list element has index zero. The end of a range is excluded, so the range from one to four produces one, two and three. These small rules explain a surprising number of early mistakes. I check them using three elements before applying a loop to a larger dataset.
Removing duplicates with a set needs justification. Two orders with the same amount can still be two separate orders. Turning their amounts into a set would remove part of the sales total. If you want to see the equivalent problem when combining tables, I cover it in my article about SQL joins.
Assigning a list does not copy it
Now I return to variables. A list is mutable: its contents can change without creating a new list. When two names refer to that same object, the change is visible through both names. Giving the data another name does not make it independent.
original = [10, 20]
alias = original
snapshot = original.copy()
alias.append(30)
print(original)  # [10, 20, 30]
print(snapshot)  # [10, 20]
print(alias is original, snapshot is original)  # True False
The is operator checks object identity, while == compares values. I use equality when comparing amounts. I do not depend on whether the interpreter happens to store two integers as the same object. An implementation optimization should not decide whether my report is correct.
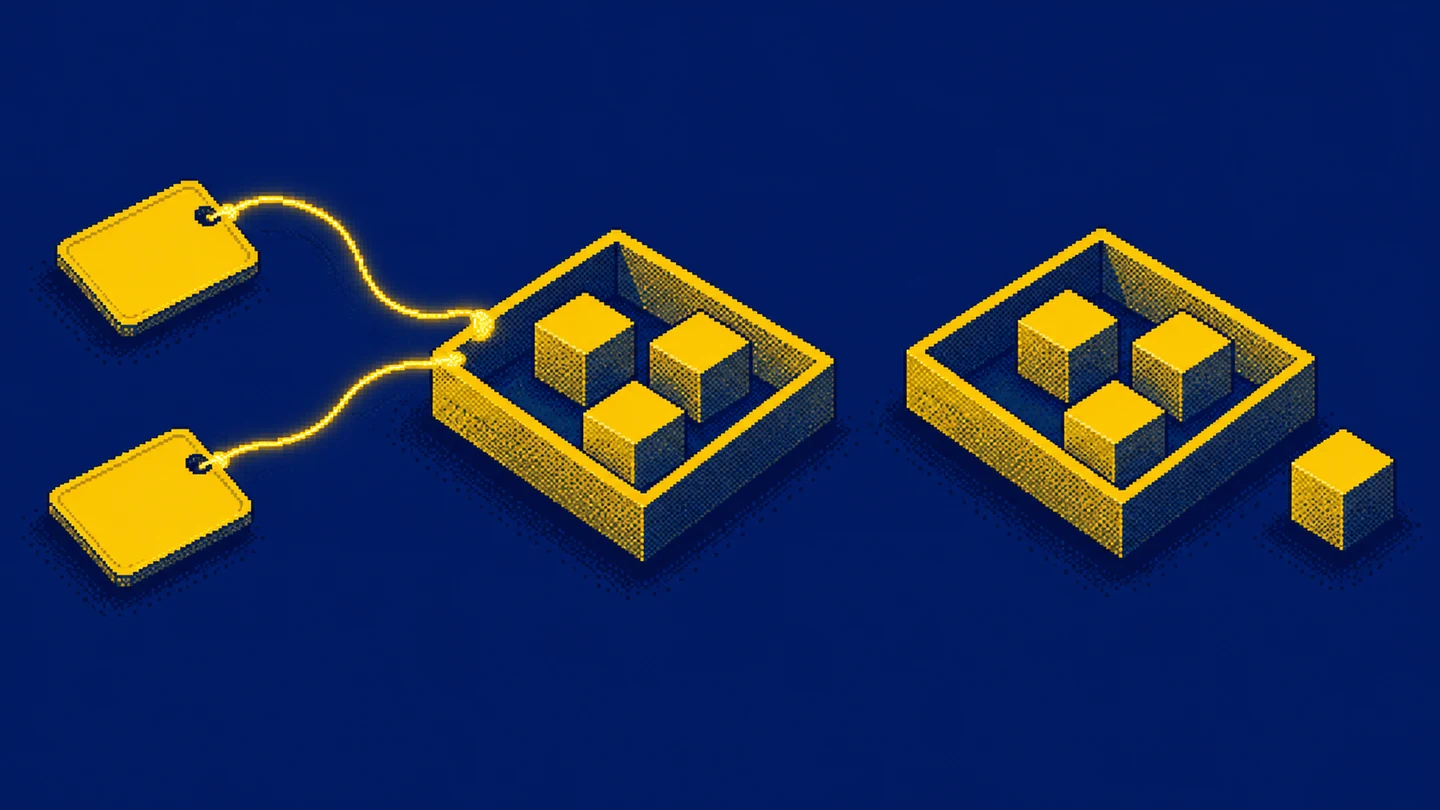
The copy method makes a shallow copy. If a list contains dictionaries, those dictionaries can still be shared. For nested data, I consider creating fresh records or using an appropriate deep copy. The copy module documentation explains both approaches and their limitations.
My practical check is straightforward: after modifying the working version, I inspect whether the source remains unchanged. That is more useful than trusting a variable called backup. Naming a list after a backup does not give it the properties of a backup. Python is impressively resistant to marketing in this respect.
Read operators together with parentheses and types
Addition, subtraction, multiplication and exponentiation use +, -, * and **. Ordinary division of two integers produces a float. The // operator performs floor division, and % returns the remainder according to the corresponding division rule.
print(7 / 2, 7 // 2, 7 % 2)  # 3.5 3 1
print(-7 // 2, -7 % 2)       # -4 1
print(2 + 3 * 4, (2 + 3) * 4)  # 14 20
print(2 ** 3)  # 8
count = 10
count += 5
count -= 3
count *= 2
count /= 4
print(count)  # 6.0
Floor division with negative values can be surprising if you expect the fractional part simply to disappear. When dividing elapsed time into buckets, I therefore check whether negative input is possible. A time correction or returned transaction can change the permitted range of values.
I use parentheses even when I remember operator precedence. A percentage-change formula communicates its intention better when the numerator and denominator are clearly separated. A zero denominator requires an explicit decision: missing result, separate category or an explanatory message. Replacing zero with one produces runnable code and an invented metric.
Augmented assignment also deserves care with mutable objects. For lists, += can modify the existing object, whereas ordinary list addition creates a new list. The expression and operator reference helps distinguish these cases.
Comparisons define which records qualify
The operators ==, !=, <, <=, > and >= describe conditions. Before writing one, I decide where its boundaries belong. Does an amount exactly equal to a hundred count as a large order? Is zero allowed? The answers should appear in both the code and the report’s definition.
amount = 100
status = "paid"
print(amount >= 100 and status == "paid")  # True
print(0 <= amount < 100)                   # False
print(status in {"paid", "shipped"})       # True
print(not (status == "cancelled"))         # True
print("" or "unknown")                    # unknown
The operators and and or short-circuit: their second operand is evaluated only when needed. They also return one of their operands, which need not be True or False. That explains the final line. The pattern can be convenient for fallback text, but with numbers it may accidentally replace a legitimate zero.
For a complicated filter, I split the logic into named conditions. I prefer to see a valid status and an acceptable amount separately instead of decoding a long chain of operators. This makes boundary cases easier to test and makes it easier to explain why a particular record entered the result.
Float is approximate, while formatting changes the display
Floating-point numbers are useful for measurements and numerical calculations, but they cannot represent every decimal value exactly. The floating-point tutorial explains the difference between decimal notation and binary representation.
from decimal import Decimal
from math import isclose
print(0.1 + 0.2 == 0.3)       # False
print(isclose(0.1 + 0.2, 0.3))  # True
print(Decimal("0.1") + Decimal("0.2"))  # 0.3
print(f"{0.1 + 0.2:.2f}")    # 0.30
Formatting to two decimal places changes presentation rather than repairing the underlying representation. For measurement comparisons, I choose a tolerance appropriate to the problem’s scale. For amounts, I consider integer minor units or Decimal constructed from text. Choosing Decimal alone does not establish rounding rules or the business definition of an amount.
In the exercise, I use cents stored as integers. Summing remains simple and the unit is explicit. This deliberately limits the example. Currency conversion or distributing a cost across several items would require additional decisions about rounding and allocating the remaining difference.
Define the input contract before combining the pieces
Even a small program needs a description of its data. Here, one dictionary represents one order, its identifier is text, its status belongs to an agreed list, and its amount contains integer cents written as text or a missing value. I write down those assumptions before calculating anything. They make unsupported records easier to recognize.
I check identifier uniqueness separately. Two equal amounts are allowed, while two rows with the same order identifier need an explanation. They might represent an export error, a history of changes or individual order items. Each interpretation requires a different response. Automatically removing repeated identifiers can remove valid information before I understand the dataset.
I also decide whether negative amounts are permitted. A refund and an accidentally typed minus sign look identical to an integer type. A type determines which operations are possible; it does not establish business validity. A paid order worth zero could be a sample, a gift or an error. The exercise deliberately treats it as valid.
When a result surprises me, I stop at the first record where the calculation differs from my expectation. I inspect the raw value, its type, the selection condition and its contribution to the total. Adding conversions at random may silence an error while making the actual processing harder to explain.
Exercise: summarize known amounts for paid orders
I have four synthetic records. I include only paid orders whose amount is available. Zero is a valid amount. Missing amounts should remain visible through a separate counter. Before running the program, I write down the expected result: two orders with known amounts, a total of twelve thousand cents, and one missing amount.
rows = [
    {"id": "A01", "status": "paid", "amount_cents": "12000"},
    {"id": "A02", "status": "paid", "amount_cents": "0"},
    {"id": "A03", "status": "cancelled", "amount_cents": "5000"},
    {"id": "A04", "status": "paid", "amount_cents": None},
]
total_cents = 0
known_count = 0
missing_count = 0
for row in rows:
    if row["status"] != "paid":
        continue
    raw_amount = row["amount_cents"]
    if raw_amount is None:
        missing_count += 1
        continue
    total_cents += int(raw_amount)
    known_count += 1
average_cents = total_cents / known_count if known_count else None
print(total_cents, known_count, missing_count, average_cents)
# 12000 2 1 6000.0
The loop takes dictionaries from the list one at a time. The continue statement moves to the next record. Indentation determines which instructions belong to the conditions and the loop. The average describes known amounts for paid orders only. I do not call it the average of all orders because the missing amount limits that interpretation.
Now change every status to cancelled. The total and known-order count should both be zero, while the average should be None. Then restore the data and add another paid order with the amount "12000". The total should rise to twenty-four thousand and the known count to three. A repeated amount still belongs to a separate record.
Finally, replace one numeric string with "missing". The program raises ValueError because that format falls outside the agreed input. This is a good point to design a report of rejected rows. Trying these changes teaches me more than repeatedly running the same comfortable example.
To apply similar reasoning to reporting, look at my SQL histogram exercise. The tool changes, but questions about units, missing values and the meaning of a row remain. I start with those questions before admiring how compact the code looks.
Key takeaways
Do I have to declare a variable's type in Python?
No. The object has a type, and a name refers to that object. You can later assign an object of another type to the same name, although doing so often makes analysis code harder to understand.
Why does changing one list affect another variable?
Assigning a second name to a list does not copy the list. Both names refer to the same object. The copy method creates a new outer list, but nested objects can still be shared.
Do None, zero and an empty string mean the same thing?
No. None can represent a missing value, zero is a number, and an empty string is text. All are false in a condition, so I check missing values explicitly with is None.
AI was used in an automated way while working on this article. If you want to learn how to do it too, check out this project.
