KajoData / statistics
How to calculate the median and interpret it alongside the mean
Calculate the median step by step, compare it with the mean, and understand ties, missing values, aggregation levels and the limits of a single summary.
The median is the centre of an ordered dataset. With an odd number of observations, choose the middle value. With an even number of numerical observations, take the arithmetic mean of the two middle values. The calculation is straightforward. Deciding what belongs in the dataset takes more thought.
I like to begin with a few values on paper before opening a spreadsheet. That gives me an expected answer and makes problems such as numbers stored as text easier to notice. A function can calculate a statistic, but it cannot decide which population the report should describe.
All datasets below are synthetic. They do not describe actual salaries, school results or customer service performance. I use them to explain calculation and interpretation. Statistics Canada introduces the median alongside the mean and mode as different measures of central tendency.
Finding the median with an odd count
Take five task durations: 9, 3, 7, 5 and 4 minutes. First arrange them in ascending order: 3, 4, 5, 7, 9. The third position is the middle one, so the median is 5 minutes. Two observations lie on each side of that central position.
For an odd observation count, the middle position is (n + 1) / 2. With five observations, that gives position three. The formula identifies a place in the ordered series. It does not calculate the median by adding one to a duration or by dividing the measured values themselves.
Ordering matters for the manual procedure. The middle cell of an unsorted column need not contain the median. In the original sequence here, the middle item was 7, but the median is 5. Arrange by value before choosing a central position.
Keep repeated values. Two tasks that each lasted four minutes are two observations. Removing a repeated number changes the dataset. Deduplication requires evidence that two records describe the same event because of an import or recording error. Equal measurements alone do not establish that.
An even count has two middle positions
Consider the numerical grade example from the earlier Polish article: 5, 5, 5, 4, 5, 2, 2, 4. Sorting gives 2, 2, 4, 4, 5, 5, 5, 5. There are eight observations, so the middle lies between the fourth and fifth positions.
Those positions contain 4 and 5. Their sum is 9; dividing by two gives a median of 4.5. That result need not be one of the observed values. Nobody has to receive exactly 4.5 for the centre calculated by this convention to be 4.5.
For even n, use positions n / 2 and n / 2 + 1, then average the values at those positions. Do not average the position numbers or arbitrarily choose the lower side. The official median definition describes this convention for numerical observations.
I treat these grades as a calculation exercise using an agreed numerical coding. Real educational interpretation also depends on the scale and the school’s rules. A median of 4.5 does not automatically become a final grade or determine an assessment decision.
Mean and median describe different properties
The eight grades sum to 32. Divide that by eight and the arithmetic mean is 4. The median is 4.5. Both are correct. The difference does not mean that one calculation needs to be adjusted until it matches the other.
The mean uses the total and count. The median uses positions in an ordered dataset. When every observation has equal weight, a mean and count allow you to reconstruct the total. A median and count do not generally preserve that information.
I therefore avoid calling the median inherently fairer. The appropriate measure depends on the question. The median can describe the centre of a skewed distribution. Planning the total time needed for a set of tasks also requires attention to the total or mean and to unusually long cases.
The Australian Bureau of Statistics explains the different sensitivity of these measures to extreme values. That is a reason to choose and label a measure deliberately. It is not a reason to remove the mean from every report.
A practical dashboard may use both. If the median stays stable while the mean rises, I want to understand which observations changed. Looking at the underlying distribution is more useful than declaring one number honest and the other misleading before investigating the data.
What one very large observation changes
Start with five synthetic service durations: 2, 3, 4, 5 and 6 minutes. Both the median and mean are 4. The total is 20, divided by five observations. Now replace the last value, 6, with 36. The ordered dataset becomes 2, 3, 4, 5, 36.
The median remains 4 because the central position has not changed. The total rises to 50, so the mean becomes 10. Moving an extreme value further from the centre can leave the median unchanged when the central positions remain unchanged.
The 36 minute case still matters. It may consume capacity, block a queue, or need a different process. A report containing only the median might hide that operational information. I would also show the observation count and some information about spread or the distribution.
An extreme value could be an error or a valid difficult case. I investigate the record before removing it. Its effect on the mean does not prove that it is wrong. Similar decisions arise in data cleaning, where deleting inconvenient observations can change the question being answered.
Ties make the usual explanation less literal
People often say that half the values are below the median and half above it. With ties, that wording can be misleading. In 1, 2, 2, 2, 9, the median is 2. Only one observation is strictly lower and one is strictly higher. Three observations equal the median.
A careful statement is that at least half the observations are no greater than the median and at least half are no less. This allows ties. In everyday reporting, describing the median as the centre of ordered observations is often enough without promising two equal groups of strictly different values.
The median also differs from the most frequent value, or mode. In 1, 1, 2, 3, 4, the median is 2 and the mode is 1. A question about the most frequently ordered quantity may therefore call for a different statistic.
This affects chart labels. “Typical result” is convenient but ambiguous. I prefer “median duration of completed tasks” with an explicit period. The reader then knows both the statistic and the group it describes, rather than having to infer them from a familiar sounding adjective.
Define what one observation represents
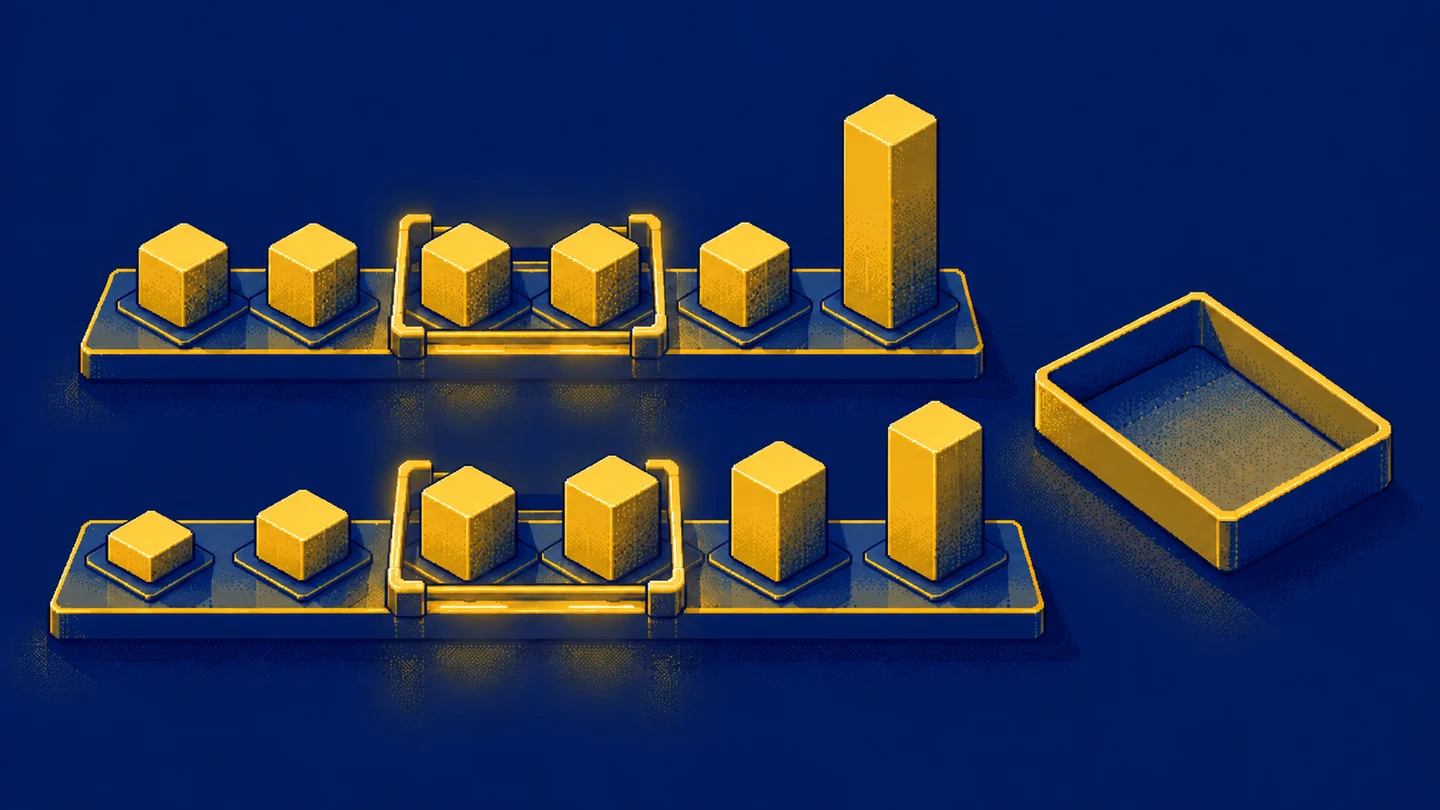
You could calculate the median order amount, the median customer’s total spending, or the median monthly sales total. Each uses a different observational unit. The amounts may come from the same company, but the measures describe different things.
In an order level dataset, a customer with ten orders contributes ten observations. In a customer spending dataset, that person contributes one total. A report reader need not know every table relationship, but should know whether the statistic describes an order, person or month.
For a small example, the first customer has three orders of 10, while the second has one order of 100. The four order amounts have a median of 10. Customer totals are 30 and 100, whose median is 65. There is no contradiction: the unit of observation changed.
Check equal weighting too. A dataset with one record per store treats a small store and a large store as one observation each. A dataset of all transactions gives more observations to the store with more purchases. If weights are required, specify an appropriate separate method rather than assuming an ordinary median formula already accounts for them.
The same issue appears when a delivery is split into several tracking events. A statistic calculated over events can describe a different process from one calculated over deliveries. I write the intended unit beside the measure before choosing a tool or polishing a chart title.
Do not combine group medians by averaging them
Suppose group A contains 1, 2, 3, while group B contains 100, 101. Their medians are 2 and 100.5. The average of those two medians is 51.25. Combine the actual observations, however, and the series is 1, 2, 3, 100, 101. Its median is 3.
Weighting those medians by group size does not generally recover the combined median either. Group centres do not preserve the positions of every observation. You need the detailed values or a representation that preserves enough of their distribution to calculate the combined statistic.
Monthly reporting creates a common version of this mistake. Taking the median of twelve monthly medians describes twelve monthly indicators. It does not generally calculate the median of all transactions during the year. Either statistic might be useful, but they need different labels.
I therefore record the aggregation level beside the result. If the request is for the annual median duration of individual tickets, I return to that year’s tickets. The same discipline helps with SQL grouping: first define the input row, then choose its summary.
Calculating a median in Excel
English Excel uses MEDIAN; Polish Excel uses MEDIANA. If the eight grade values are genuine numbers in A2:A9, =MEDIAN(A2:A9) returns 4.5. In Polish Excel the formula is =MEDIANA(A2:A9), with the result displayed using the appropriate decimal separator.
You do not need to sort the worksheet physically before using the function. Sorting above explains the manual definition. Sorting one value column without its related identifiers could damage the relationships between fields, so I keep the source together and calculate the statistic separately.
The Microsoft reference states that text, logical values and empty cells in an array or reference are ignored, while zero is included. A number stored as text inside the supplied range may therefore disappear from the calculation. Missing and zero are different data states.
Consider 0, 2, 10. The median is 2. If zero was actually a missing measurement code and an agreed rule excludes it, the remaining known durations have a median of 6. That changes the population of observed values rather than merely changing a cell’s appearance.
Before applying the formula, I check the count of valid numerical observations and record missing values separately. For two reporting periods, the same handling rule must apply to both. Otherwise an apparent change in the process may simply reflect a different import or missing value convention.
I also inspect the selected range. A formula that accidentally includes another team’s rows can return a plausible number with no error message. A small expected example helps with arithmetic, but the actual report also needs a scope check against its stated definition.
Context matters as much as the central value
Two datasets can have the same median and very different spreads. The median of 4, 5, 6 is 5. The median of 1, 5, 100 is also 5. The second series includes much more varied experiences. A single measure of centre cannot show that difference.
Team comparisons require comparable tasks. If one group handles quick requests and another handles complex complaints, duration medians alone do not rank work quality. Start and end definitions, excluded records and case mix may explain more than the difference between the two central values.
Unfinished observations deserve separate attention. A median based only on closed tasks does not tell you how long currently open tasks have waited. If long cases remain open, the completed task report may look healthy while the queue worsens. I would show the number and age of open cases separately.
For a very small dataset, I often display all observations. Three durations fit comfortably in a tiny table. The reader can then see whether the central value describes a recurring process or happens to lie between three very different cases. A large dashboard is not a prerequisite for a useful explanation.
These checks also affect comparisons over time. If a new system records short tasks that the old system omitted, the median may fall without any existing task getting faster. I want a stable observation definition before treating a movement in a statistic as evidence of improvement.
Compare the same measurement and time window
For a duration report, specify the start and end events. Receiving a ticket and assigning it are different possible starts. Resolving a case and having the solution accepted are different possible ends. A correct formula cannot make two incompatible measurement definitions comparable.
The time window needs a rule as well. Tasks started in October need not be the same set as tasks completed in October. State which rule you used. Also check units before combining sources: a value of five minutes and a value of five hours can look identical in a poorly labelled column.
For the first example, I would report: “The median of five measured durations is 5 minutes; observed durations range from 3 to 9 minutes.” That states the unit, count and context. It does not promise that the next task will finish within five minutes. Add the number of missing measurements and any relevant exclusions beside the result.
Exercise: calculate and defend the interpretation
Take seven synthetic durations: 8, 3, 4, 20, 5, 4 and 12 minutes. Ordered, they are 3, 4, 4, 5, 8, 12, 20. The median is 5. The total is 56, so the mean is 8. Explain in ordinary language how both answers can describe the same dataset.
Replace 20 with 48. The median remains 5 while the mean increases to 12. Would a capacity planning report be complete with only the median? The answer depends on its purpose, but the long case does not stop consuming time merely because it leaves the central position unchanged.
Finally, add an eighth observation whose duration is missing. Do not invent a value to fill the gap. State that the median describes seven known durations and that one measurement is missing. That is more useful than entering zero just to make the column look complete. Reliable calculation starts with an honest account of the observations.
Key takeaways
How do I find the median with an even number of values?
Sort the values and average the two middle ones. For 2, 2, 4, 4, 5, 5, 5, 5 the median is 4.5.
Is the median always better than the mean?
The choice depends on the question. The median describes the ordered centre and is less sensitive to extremes, but does not reconstruct the total or show the entire spread.
Can I average monthly medians?
That summarises monthly indicators, but generally does not produce the median of all annual observations. Return to the underlying data for that measure.
AI was used in an automated way while working on this article. If you want to learn how to do it too, check out this project.