KajoData / SQL
WHERE in SQL: filters, NULL and date boundaries
I filter six orders to select an October population, showing how parentheses, missing statuses and month boundaries change the result.
The most awkward WHERE bug is one that allows the query to run. You get numbers, the chart looks plausible, and the report quietly covers a different set of orders from the one you intended. I therefore start filtering with a plain sentence: which records should remain, and why?
Here I will select orders from Poland created in October, with an allowed status and a positive amount. Along the way I will explain missing end-of-day records, parentheses around AND and OR, and NULL. The examples target PostgreSQL 18 and use six synthetic records small enough to inspect by hand.
What WHERE does to a row
WHERE evaluates a condition against the query’s input data. Rows continue when that condition is true. False and unknown results do not pass. The table expressions documentation describes this rule.
The SELECT list determines the visible output columns. WHERE determines which records can reach that output. I can filter by country without displaying country in the final table. The condition needs access to the field through its source, but the field does not have to be exposed to the reader.
In the written statement, WHERE follows FROM and any JOIN clauses and precedes GROUP BY, HAVING, and ORDER BY. This describes structure and logical meaning. The engine chooses a physical way to retrieve the data. The written sequence of conditions does not promise a particular sequence of execution steps.
Six orders and one concrete question
Assume the following source data. Each record represents one order, the amounts use arbitrary units, and created_at is a timestamp without time zone. All times in this example refer to the same local clock.
| order_id | created_at | status |
|---|---|---|
| 1 | 2026-10-01 09:00:00 | ready |
| 2 | 2026-10-31 18:00:00 | shipped |
| 3 | 2026-11-01 00:00:00 | ready |
| 4 | 2026-10-15 10:00:00 | cancelled |
| 5 | 2026-10-20 12:00:00 | NULL |
| 6 | 2026-10-22 08:00:00 | shipped |
The country and amount for the same six orders appear below. These are further columns of one source, separated for readability.
| order_id | country | amount |
|---|---|---|
| 1 | PL | 100 |
| 2 | PL | 50 |
| 3 | PL | 80 |
| 4 | DE | 200 |
| 5 | PL | 0 |
| 6 | DE | NULL |
The question is: which PL orders were created in October 2026, have a ready or shipped status, and have an amount greater than zero? I expect records 1 and 2. Each remaining order fails for a specific reason: a November date, a different country, an unaccepted status, or an unsuitable amount.
The following statement provides a source for one query. In the later examples, retain the WITH section and replace the SELECT that follows it. VALUES is simply a way to supply this small illustrative dataset.
WITH orders(order_id, created_at, status, country, amount) AS (
    VALUES
        (1, TIMESTAMP '2026-10-01 09:00:00', 'ready', 'PL', 100),
        (2, TIMESTAMP '2026-10-31 18:00:00', 'shipped', 'PL', 50),
        (3, TIMESTAMP '2026-11-01 00:00:00', 'ready', 'PL', 80),
        (4, TIMESTAMP '2026-10-15 10:00:00', 'cancelled', 'DE', 200),
        (5, TIMESTAMP '2026-10-20 12:00:00', NULL, 'PL', 0),
        (6, TIMESTAMP '2026-10-22 08:00:00', 'shipped', 'DE', NULL)
)
SELECT order_id, amount
FROM orders
WHERE country = 'PL'
  AND created_at >= TIMESTAMP '2026-10-01 00:00:00'
  AND created_at < TIMESTAMP '2026-11-01 00:00:00'
  AND status IN ('ready', 'shipped')
  AND amount > 0
ORDER BY order_id;| order_id | amount |
|---|---|
| 1 | 100 |
| 2 | 50 |
Compare numbers and text deliberately
I use = for equality and <> for inequality. The operators >, >=, <, and <= define boundaries. The comparison reference describes their behaviour, including comparisons of nonnumeric types. Here, amount >= 100 admits orders 1 and 4, while amount > 100 admits only order 4.
A text value goes in single quotes: country = 'PL'. The numeric values in this example do not need quotes. I do not want the query to depend on an accidental conversion from text to a number. If an import has placed amounts in a text column, I first need to establish their format and prepare them appropriately.
For a precisely defined country code, I choose equality. The field name still needs a definition: shipping country, customer country, and document country can be different. No operator can resolve that business choice for me. The synthetic source has one agreed country code, but a real report should record what event or entity it describes.
I also avoid making universal assumptions about letter case from one successful comparison. Text comparisons depend partly on their configuration. If a source mixes PL, pl, and extra spaces, I need a normalisation policy. I cannot simply assume that every database engine will treat those values as equivalent.
AND, OR, and parentheses
AND requires both conditions to hold. OR accepts at least one. In PostgreSQL, AND binds more tightly than OR; the lexical structure reference documents precedence. When combining the operators, explicit parentheses make the intended grouping easy to inspect.
SELECT order_id
FROM orders
WHERE country = 'PL'
  AND (status = 'ready' OR status = 'shipped')
ORDER BY order_id;
The result contains 1, 2, and 3. I have deliberately left out the date and amount conditions to isolate the status rule. Every returned record must belong to PL and have one of the two permitted statuses.
Remove the parentheses and the condition means (country = 'PL' AND status = 'ready') OR status = 'shipped'. Order 6 now qualifies because shipped is sufficient regardless of country. The database reports no syntax error. It received a valid request describing a different set of rows.
When reviewing a filter like this, I look for an alternative branch that can bypass a compulsory condition. Country, month, or document type often needs to apply to every branch. One extra OR line can accidentally broaden the report beyond those boundaries. Parentheses are a small cost compared with explaining the resulting discrepancy later.
IN makes an allowed list easier to read
For the two statuses I can write status IN ('ready', 'shipped'). In our example, this replaces the parenthesised pair of equalities joined by OR. It makes the list’s connection to one field explicit. The benefit becomes more obvious when more statuses are added.
An IN list is not a text pattern. The value 'ship' does not automatically match 'shipped'. If the business introduces a new status, somebody needs to decide whether it belongs in the report and deliberately update the list. Similar-looking names do not establish the same business meaning.
I handle NOT IN and NULL separately. If an exclusion list contains NULL, a value that does not match another list item can produce an unknown result. The IN and NOT IN documentation explains the trap. Adding NULL to a list does not mean “also include missing statuses.” I use an explicit IS NULL condition for that decision.
NULL does not mean false or zero
The condition status = NULL does not find missing statuses. The appropriate expression is status IS NULL, which identifies order 5 here. To select known values I can use IS NOT NULL. The comparison reference describes these predicates and their distinction from ordinary equality.
SQL includes an unknown logical result. Comparing the missing amount with zero does not produce true, so order 6 fails amount > 0. It also fails amount <= 0. A missing amount does not automatically belong to either of the two numeric categories.
This matters when describing the report. Selecting “all orders other than cancelled” with status <> 'cancelled' also removes order 5. Its missing status is not known to differ from cancelled. If the business wants missing statuses included, write (status <> 'cancelled' OR status IS NULL) and make that policy visible in the report definition.
The logical operator tables also show that true OR unknown is true, while false AND unknown is false. A NULL in one part does not determine the whole condition by itself. Follow the complete expression, especially when it has several alternative branches.
Represent a month with an exclusive end
The main query includes the beginning of October and excludes the beginning of November. Order 2, created at six in the evening on the final day, stays in the result. Order 3, created exactly at the next month’s midnight, is excluded. There is no need to guess the final fractional second in October.
BETWEEN includes both endpoints. For a timestamp column, an interval between midnight on 1 October and midnight on 31 October does not include the entire final day. This commonly produces an understated result. A date in a requirement is not enough to establish how its hours should be treated.
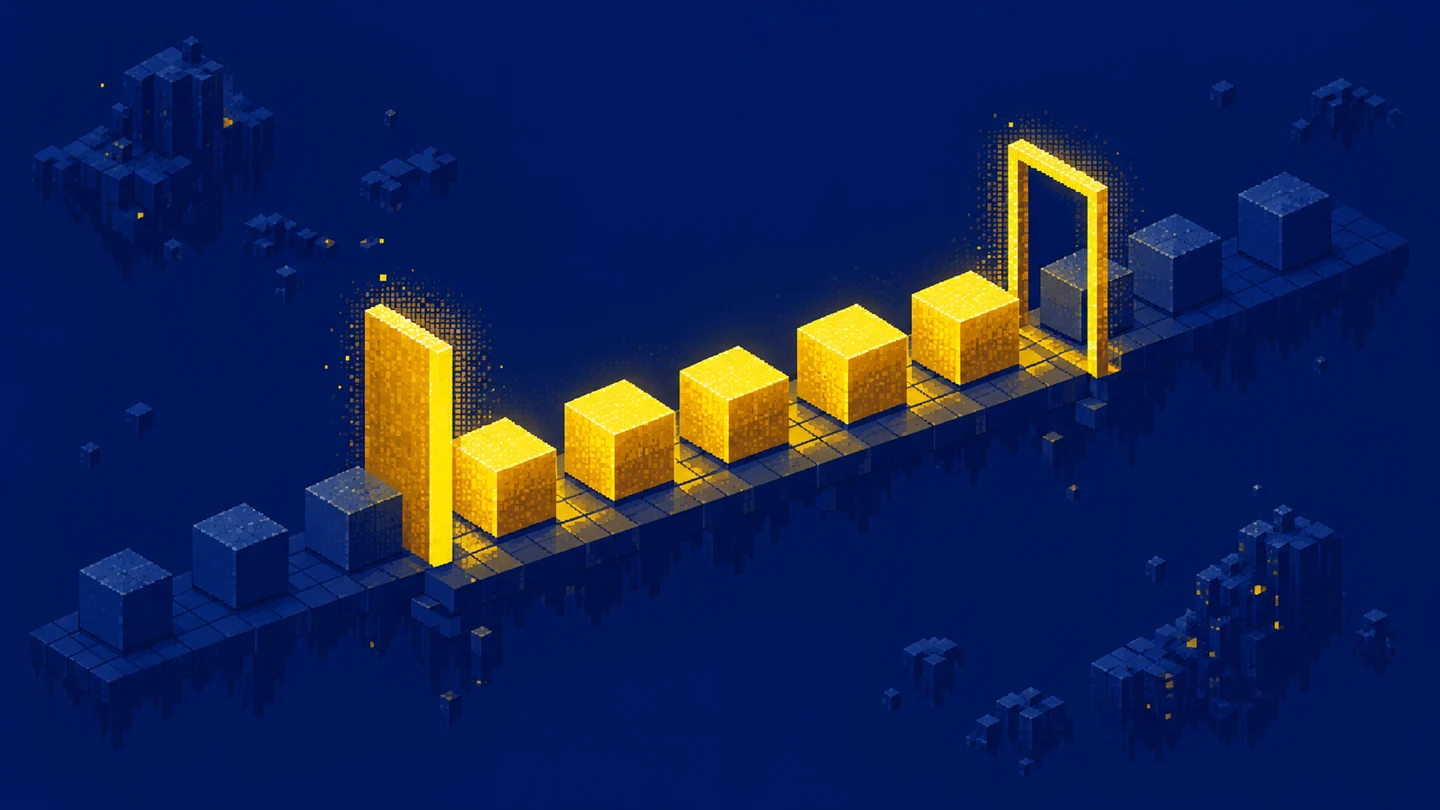
An interval written as >= start and < next_start can be placed next to another month without counting their shared boundary twice. January ends where February begins, but only one of the two filters contains that instant. This is useful when reports compare adjacent periods.
This article uses timestamps without time zones. For real events stored as timestamptz, define the reporting time zone and the corresponding boundary instants. The date and time documentation distinguishes those types. Our simple local-clock example should not be copied unchanged into a global event system.
LIKE describes a pattern
The condition status LIKE 'ship%' matches shipped in our dataset, returning orders 2 and 6. The percent sign represents a sequence of characters, while an underscore represents one character. The pattern matching reference also describes escaping special characters.
For a closed list of statuses, I keep IN. LIKE is useful when the requirement actually describes a pattern. If I need a literal underscore in a product code, I must account for its special role. Copying part of a name into a pattern without considering that role can select more records than intended.
I do not treat LIKE as regular-expression syntax. Square brackets are not a universal way to specify alternative letters here. Engine-specific extensions need their own documentation. This tutorial uses two simple wildcard symbols and explicitly identifies PostgreSQL as its dialect.
WHERE, HAVING, and output aliases
WHERE filters rows before grouping. HAVING filters groups. If I want individual orders with positive amounts, I use WHERE. If I want countries whose order total exceeds a threshold, I need grouping and a condition on an aggregate. Those questions operate at different levels of detail.
I therefore cannot use SUM(amount) > 100 as an ordinary WHERE condition at the same query level. First I must decide which rows belong in the total. Removing some rows before aggregation changes that metric even if the final threshold stays the same. A familiar-looking condition can conceal a very different calculation.
Similarly, an alias introduced in SELECT is unavailable in WHERE at that level. If a calculation needs a name and then a filter, I can prepare it in a subquery. See the explanation of SQL clause order and the HAVING entry for the next stage.
Inspect boundaries and excluded records
I break the main requirement into simple questions. PL leaves four records. Restricting those to October leaves three: 1, 2, and 5. The allowed statuses leave 1 and 2. Requiring a positive amount does not change that final pair. These counts follow directly from the small source table.
Then I look for boundary cases: exactly at the start, exactly after the end, equal to the amount threshold, and missing a status. A dataset containing only obvious matches does not establish whether exclusions are defined correctly. Two conditions can agree on the typical record while differing precisely at a boundary.
With a large source, inspecting the first few output records cannot establish that all other rows are correct. That is why I keep a short definition of the selected population and the reasoning behind exceptions. Another person should be able to assess the intention without reconstructing every conversation that led to the report.
Exclusion reasons do not necessarily add up
One order can belong to another country, have a missing amount, and have an unaccepted status simultaneously. Counting each failure separately can produce a total larger than the number of rejected records. That does not establish an error in WHERE. Those counters describe overlapping categories.
I distinguish two ways to report this. I can show every failed condition for each record, or assign one primary reason according to an agreed priority. In the second approach, that priority is my reporting rule. It does not describe the engine’s physical evaluation order. The reader should know which approach the report uses.
Order 5 has both a missing status and a zero amount. Removing the amount filter still does not let it pass the accepted status list. Consequently, the increase after relaxing one condition does not necessarily identify every row that previously failed that condition. Other restrictions still apply.
Creation time and the time represented by status
Filtering an October creation date does not establish that the displayed status describes the end of October. The source may hold the current order status and update it during November. Such a report describes October orders using the state available when read. That differs from the state of orders at the close of the month.
A historical view requires suitable data: a change history or an agreed snapshot. Adding another WHERE condition cannot reconstruct information that was never recorded. Before publishing, I therefore establish both the date that qualifies an event and the time represented by its other attributes. This helps explain why reading the report again a week later might produce a different population.
Logical conditions and query speed
Moving a condition higher in an AND list does not guarantee that PostgreSQL evaluates it first. The engine can change how expressions are evaluated. The expression evaluation rules explain why correctness must not depend on an expected left-to-right sequence.
For example, I do not treat the first condition as universal protection against an error in a later calculation. When dividing by a field that might be zero, I need an expression that handles that case, such as a deliberately applied NULLIF. Placing a filtering condition before the division in the written query does not supply that guarantee.
If a query is slow, I examine its plan, data volume, and available indexes. EXPLAIN helps reveal the selected execution approach. Six example records cannot support a specific performance promise. I first define the correct population and then investigate an efficient way of obtaining it.
Exercise: include missing statuses deliberately
Change the requirement: include all October PL orders with ready, shipped, or missing status, regardless of amount. Remove the amount condition and use (status IN ('ready', 'shipped') OR status IS NULL). Keep country and both time boundaries as compulsory AND conditions.
The expected identifiers are 1, 2, and 5. Order 3 still fails the November boundary, while orders 4 and 6 fail the country requirement. If your reasoning yields more rows, inspect the parentheses. If it yields fewer, check whether you used ordinary equality for NULL or accidentally kept the positive-amount condition.
Finally, describe the result to the report’s reader in one sentence. Say that missing statuses were deliberately included. That decision affects how the order count should be interpreted. A finished query should make sense both in the editor and in a conversation about what was actually counted.
Key takeaways
Does WHERE choose columns?
WHERE chooses rows satisfying a condition. SELECT defines the visible columns, and a field used for filtering need not be displayed.
How do I find missing values?
Use IS NULL. An ordinary comparison with NULL produces an unknown result that does not pass WHERE.
How do I include a full month of timestamps?
The example includes the start of the month and excludes the start of the next. Time-zone-aware data also requires an explicit reporting time zone.
AI was used in an automated way while working on this article. If you want to learn how to do it too, check out this project.