KajoData / SQL
SQL clause order: from source rows to the final result
Follow six orders through filtering, grouping and a limit. I explain aliases, ties, join cardinality and why logical order differs from the database plan.
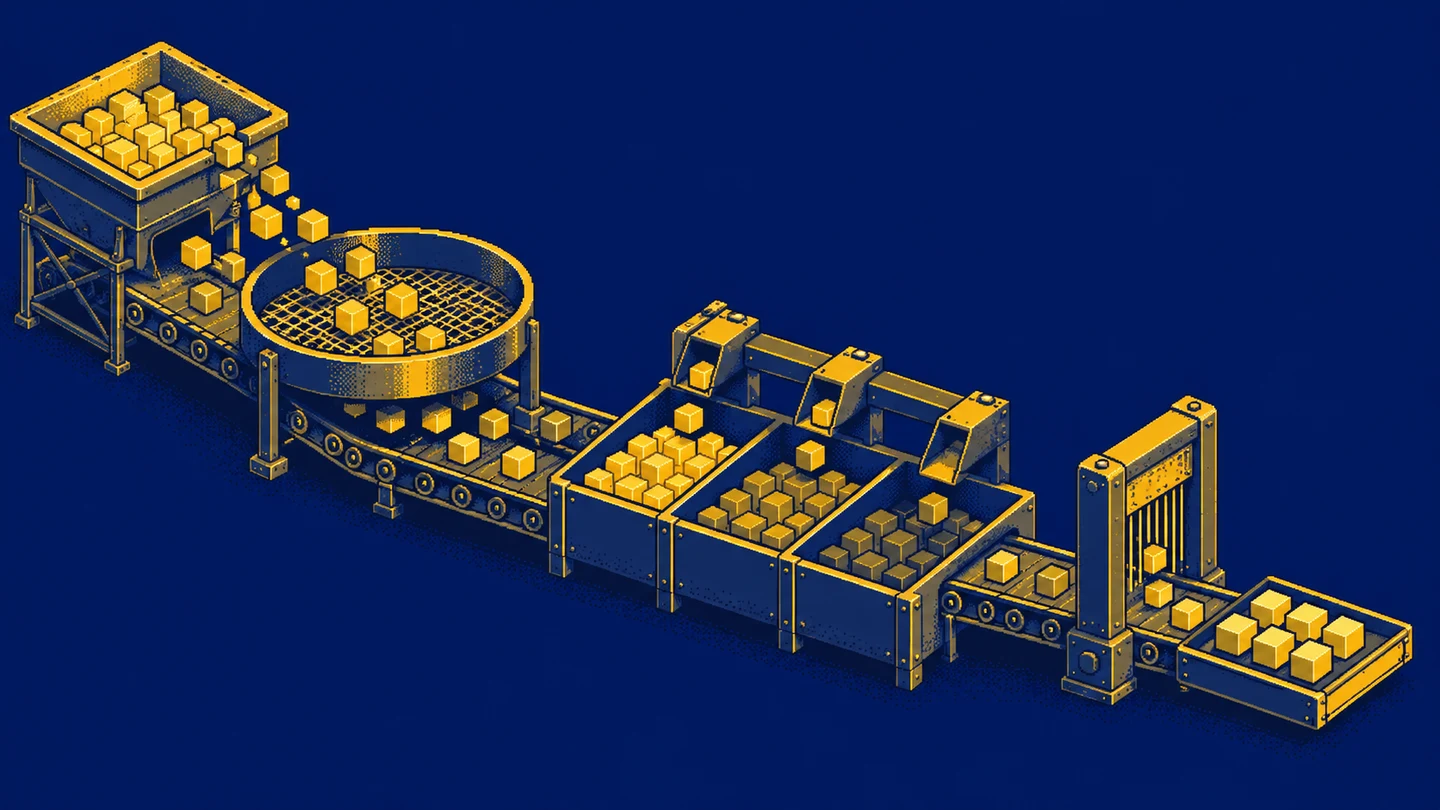
You write SELECT at the top of a query, then try to use one of its aliases in WHERE. The database says the column does not exist. Yet the same name works in ORDER BY. When I explain SQL, this is a useful place to stop and ask what order we are actually talking about.
There are three different things here: the order of clauses on the page, the logical meaning of the query, and the physical plan chosen by the database. Keeping them separate makes error messages less mysterious. It also helps you explain why a report changed after a seemingly harmless edit.
The examples use PostgreSQL 18 and small synthetic datasets. I derive the expected results from the documentation and the rows shown here. I am not presenting execution logs or measured performance. If the basic statement is still unfamiliar, start with my introduction to SELECT.
Written order and logical order
A familiar query starts with SELECT, followed by FROM, WHERE, GROUP BY, HAVING, ORDER BY, and LIMIT. That written order lets you state the desired output first. To understand the result, I usually start with the source and follow the transformations towards that output.
For a single straightforward query, this is the working model I use:
| Logical stage | Question it answers |
|---|---|
| FROM and JOIN with ON | Which rows form the input? |
| WHERE | Which input rows remain? |
| GROUP BY and aggregates | Which groups and summaries do I calculate? |
| HAVING | Which groups remain? |
| Window calculations | What do I calculate over the remaining rows or groups? |
| SELECT list | Which values become output columns? |
| DISTINCT | Which duplicate output rows disappear? |
| ORDER BY | How do I arrange the output? |
| OFFSET and LIMIT | Which portion of that output do I return? |
This is a reasoning aid for a particular query level. It does not attempt to cover every feature, including set operations and row locking. The full PostgreSQL SELECT reference describes those cases. I have separated window calculations conceptually even though their expressions are normally written in the SELECT list.
You can omit most of these clauses. A query without grouping still makes sense. A query without WHERE uses all rows from its specified source. A query without sorting can return rows, but it promises no particular presentation order. Missing clauses do not imply invisible business rules.
A report small enough to follow by hand
Suppose I want the sales channel with the largest total amount from paid orders. A channel qualifies only if it has at least two paid orders. Each source row represents exactly one order. Amounts use a single arbitrary unit; there are no hidden currency conversions or tax adjustments.
| order_id | channel | status | amount |
|---|---|---|---|
| 1 | web | paid | 40 |
| 2 | web | paid | 60 |
| 3 | web | cancelled | 900 |
| 4 | store | paid | 80 |
| 5 | store | paid | 10 |
| 6 | partner | paid | 200 |
Here is the complete statement. Its source is a VALUES expression, so the example does not depend on a database download, a missing screenshot, or a table created somewhere in an earlier lesson.
SELECT
    channel,
    COUNT(*) AS paid_orders,
    SUM(amount) AS total_amount
FROM (VALUES
    (1, 'web', 'paid', 40),
    (2, 'web', 'paid', 60),
    (3, 'web', 'cancelled', 900),
    (4, 'store', 'paid', 80),
    (5, 'store', 'paid', 10),
    (6, 'partner', 'paid', 200)
) AS orders(order_id, channel, status, amount)
WHERE status = 'paid'
GROUP BY channel
HAVING COUNT(*) >= 2
ORDER BY total_amount DESC, channel ASC
LIMIT 1;
The expected output is web, a count of 2, and a total of 100. The largest individual paid order belongs to partner, but partner does not win this report. Following the stages explains why. Memorising a list of keywords without following the rows would leave that crucial detail unexplained.
FROM establishes the source and WHERE narrows it
The FROM expression provides six rows and four named columns. Here I can see every value directly. In another report, the source might be a table, view, subquery, or join. Either way, I need to know what one source row represents before I start adding amounts.
WHERE status = 'paid' removes order 3. Five rows remain. Its amount of 900 does not contribute to any subsequent channel total. I am not calculating a grand total and subtracting a cancelled amount afterwards. I am choosing which observations belong in the analysis before summarising them.
That choice comes from the question. If the report asked for all orders regardless of payment, the filter would be wrong despite being valid SQL. I therefore write the scope in an ordinary sentence before thinking about clever query construction. A database can produce a precise answer to a badly defined question.
A missing status adds another decision. A comparison such as status = 'paid' does not keep a NULL status, because the condition does not evaluate to true. To identify missing values, use IS NULL. The PostgreSQL comparison reference explains this behaviour. Whether missing statuses belong in a separate quality report is a business decision.
GROUP BY changes the grain and HAVING selects groups
After filtering, grouping by channel produces three groups. Web contains two orders totalling 100. Store contains two totalling 90. Partner contains one totalling 200. The grain of the report is now one row per channel rather than one row per order.
HAVING COUNT(*) >= 2 keeps web and store. Partner disappears even though its amount is higher. It fails the qualifying condition. Only after deciding which groups qualify do I choose the largest qualifying total. Changing the order of those decisions changes the question being answered.
Compare two requests that sound similar in conversation. “Show channels whose total exceeds 90” calls for HAVING SUM(amount) > 90. “Sum only orders whose individual amount exceeds 90” calls for a condition in WHERE. On our data, the second request keeps only the partner order before grouping.
The table expressions documentation distinguishes these levels of filtering. I work through additional cases in WHERE, GROUP BY and HAVING. Moving a condition between clauses requires checking its meaning, even when a small change seems to make the statement look tidier.
Another useful check concerns missing amounts. COUNT(*) counts rows; COUNT(amount) counts nonmissing amounts. Neither name should be chosen just because it is shorter. If an order exists but its amount is missing, those two counts answer different questions. That difference matters before anyone interprets the average or the completeness of the report.
SELECT shapes and labels the result
The select list defines three output columns. total_amount labels the value calculated by SUM(amount). That alias does not add a permanent column to the source table. It names an output expression at this query level.
In PostgreSQL, I cannot use that output alias directly in WHERE or HAVING at the same level. I write SUM(amount) in the HAVING condition, but can use total_amount in ORDER BY. PostgreSQL also permits output names in certain GROUP BY uses. The logical model helps explain name visibility, but the precise dialect rules still matter.
If I want to filter an already calculated output column by its alias, I can place the calculation in a subquery or CTE. The outer query then receives that column as input. This also helps when an expression is long enough that repeating it makes the statement hard to review.
I do not assume that every added CTE makes a report faster. A named stage can make responsibilities clearer without changing the physical work. Query organisation and performance are related topics, but they need different evidence. A readable statement remains useful even when its plan is identical to the earlier version.
The select list reference is useful when column labels and available expressions become confusing. I prefer explicit column names while learning. Grouping by a positional number may be supported, but reordering the output list can then change what that number refers to.
ORDER BY and LIMIT specify which answer you receive
Two groups remain after HAVING. Sorting by descending total puts web before store, and LIMIT 1 returns web. The amount of 100 describes the whole qualifying web group. It is not the largest individual amount from that channel.
I included channel ASC as a second sort key. It makes no difference when totals are 100 and 90. If the two totals were both 100, however, store would precede web under the ordering of these particular names. The report would have an explicit tie rule instead of an accidental winner.
Without ORDER BY, “the first row” is incomplete. Insertion order, an index, or yesterday’s screenshot does not guarantee the next result’s order. The references for sorting and LIMIT explain why limiting should be paired with an unambiguous ordering.
Adding OFFSET 1 LIMIT 1 would skip the first qualifying group and return store. It would not skip order 1 from the original input. Pagination applies to the query’s output rows, whose meaning may be very different from that of its source rows.
Understand JOIN before trusting the total
The main example deliberately has one source. A real report often joins several tables, and that introduces another question: does one resulting row still represent an order? It might now represent an order line, delivery event, or another detail attached to an order.
If an order worth 40 joins to three order lines, its amount appears on three joined rows. A later sum may therefore produce 120. Knowing that aggregation follows the join is useful only if you also inspect the join’s cardinality. Applying DISTINCT at the end does not provide a general solution to duplicated business amounts.
With a LEFT JOIN, filter placement matters too. A condition on the right table inside ON restricts matching rows while preserving unmatched left rows. The same condition in WHERE may discard those rows because the right column is NULL. I inspect the unmatched cases before moving a filter.
My first checks are counts and a few identifiable records. I want an order with no detail rows and an order with several detail rows. Then I add the aggregate. Otherwise an inflated total can look pleasantly convincing while the report quietly changes its unit of observation.
DISTINCT and windows add their own questions
DISTINCT compares complete selected rows. Selecting distinct channel names produces one occurrence of each channel. Adding the order ID changes the comparison: channel and ID combinations may all be different. You no longer requested one row per channel merely because channel remains visible in the output.
For a window calculation, I ask which rows the window can see. The window tutorial describes rows remaining after filtering, grouping, and HAVING at that level. A ranking calculated after excluding a region therefore ranks the remaining data, rather than the original full population.
In PostgreSQL 18, filtering an alias produced by ROW_NUMBER() requires another query level. Calculate it inside, then filter outside. Other systems may offer QUALIFY, but that is not the syntax used here. Copying a clause from a different product needs more checking than copying its keyword.
I introduce these features one at a time. First I want a reliable explanation for the six orders. Then I add a mechanism and ask what it changed: row count, scope, grain, or presentation. That makes a mistake traceable to a decision instead of turning the whole query into an opaque block.
The physical plan answers a different question
A database can use an index, choose a permitted join order, perform hash aggregation, or avoid a separate sort. It need not materialise every FROM row before considering a WHERE condition. The logical stages define the meaning the chosen implementation must preserve.
Use EXPLAIN to inspect that implementation. A clause’s position on the page does not tell me how many disk pages were read or how long a query took. Claims that a particular formatting convention automatically speeds up a report need better evidence.
Likewise, do not rely on left to right execution of conditions joined by AND. Preventing an invalid calculation requires an appropriate expression, rather than faith that an earlier written condition will always protect it. Expression evaluation is a separate topic, but the same script reading habit often causes both misunderstandings.
Operator precedence inside a filter
Clause order is separate from the way operators bind within a condition. In PostgreSQL, AND binds more tightly than OR. For paid orders from either web or store, I write:
WHERE status = 'paid'
  AND (channel = 'web' OR channel = 'store')
Without the parentheses, the condition means paid web orders or any store order. An unpaid store order would qualify. Our main dataset has no such row, so it would fail to expose this mistake. That is a useful reminder to choose examples that can distinguish an intended rule from a plausible wrong one.
The operator precedence reference defines how the expression is grouped. It does not promise a physical evaluation sequence. I add parentheses for the reader even when I know the default precedence.
When reviewing someone else’s report, I start with the source, joins, and date range. Then I explain which rows disappear and what one grouped row means. Finally I check output labels, sorting and tie rules. Only after the meaning is clear do I turn to performance. That order helps me improve the report that the reader actually needs.
Exercise: predict one change at a time
Raise the main query’s qualifying count to three. The expected result is empty. Web has three rows in the original source, but only two survive the paid status filter. The qualification uses the surviving orders. Explain that distinction before changing anything else.
Now restore the threshold of two and remove the status filter. Web has three orders and a total of 1000. That is valid arithmetic for the changed scope, but it includes a cancelled order. An impressive looking output can be an accurate answer to the wrong reporting question.
Finally, restore the filter and remove LIMIT. The output contains web with 100 and store with 90, in that order. Write the counts beside the stages: six source rows, five retained rows, three groups, two qualifying groups, and one final row when the limit returns. I find that small reconciliation far more useful than reciting the clause names without looking at the data.
Key takeaways
Does SQL execute SELECT first?
SELECT is written first, but logically its output expressions use the source after filtering and grouping. The physical plan is a separate concern.
Why does an alias work in ORDER BY but not WHERE?
PostgreSQL allows output aliases in ORDER BY, but not in WHERE or HAVING at the same query level. A subquery exposes the alias as input to an outer query.
Does LIMIT 1 return the largest value?
Only if the appropriate ORDER BY places it first. Add a tie breaker when a single deterministic winner is required.
AI was used in an automated way while working on this article. If you want to learn how to do it too, check out this project.