KajoData / SQL
MySQL ROWS UNBOUNDED PRECEDING: running totals and window frames
I turn six events into running totals and explain why events sharing a date require an explicit decision about order and reporting detail.
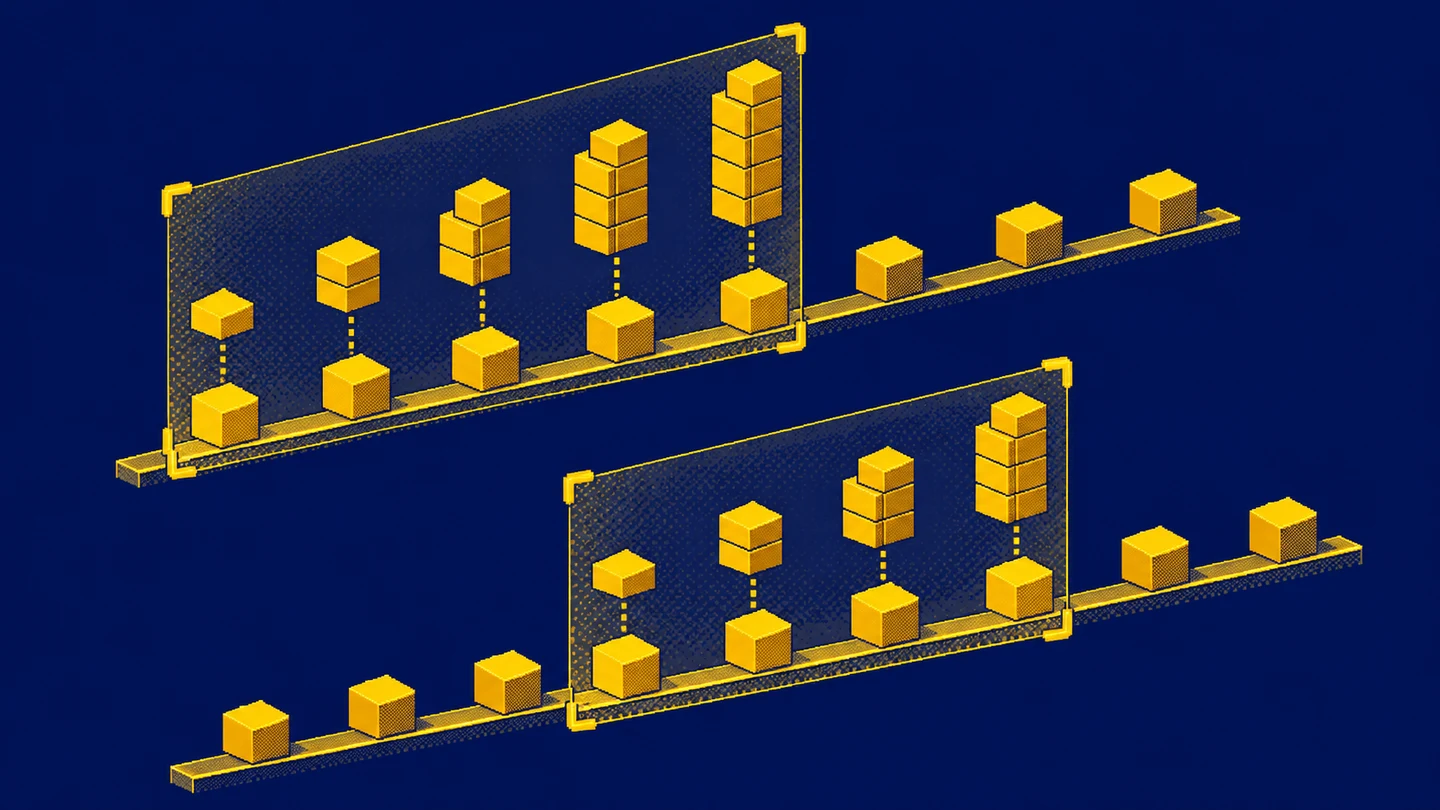
A running total sounds simple: add everything that came before to the current value. But what counts as “before” when two events share a date? And which starting point should you use: the entire table, a customer, an order or the current month?
I break the task into three decisions: partitioning, ordering and calculation boundaries. Only then do I assemble the window function. This guide uses MySQL 8.4 and small synthetic data. I do not assume that the name of a frame can establish the business meaning of a report on its own.
Partition, order and frame
A partition is a group of rows processed separately. PARTITION BY account_id separates accounts. ORDER BY inside OVER establishes their calculation order. The frame specifies which positions from that partition contribute to the result for a particular row.
A window function lets you keep individual events and attach an aggregate beside them. Ordinary grouping produces a different shape: one row per group. The MySQL window function introduction explains this basic difference. Keeping detail is useful when the reader needs both an event amount and its cumulative context.
I picture ordered slips of paper for one account. For the first slip, I sum that slip alone. For the second, I sum the first two; for the third, the first three. This is a useful picture of a running total. I still need to decide how to arrange the slips and where a new stack begins.
What UNBOUNDED PRECEDING means
ROWS UNBOUNDED PRECEDING is shorthand for ROWS BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW. The start is the partition’s first position. The end is the current position, included. The MySQL 8.4 frame specification documents the full syntax.
In a guide, I prefer the full expression because both boundaries are visible. The shorthand is also valid in team code when everyone understands its meaning. UNBOUNDED does not mean the entire table. The boundary still belongs to a particular partition, which depends on the definition inside OVER.
I would not describe ROWS as the order in which records happen to be stored on disk. It concerns positions in the window ordering. Without appropriate ordering, the label “running” is insufficiently defined. The database cannot guess whether event time, posting time or import order is the relevant chronology.
Six events and a complete first example
I use events belonging to two fictional accounts. Amounts are synthetic units, and a negative amount represents a correction. event_id explicitly breaks ties between events on the same date.
| account_id | event_id | event_day | amount |
|---|---|---|---|
| A | 1 | 2026-01-01 | 100 |
| A | 2 | 2026-01-02 | 50 |
| A | 3 | 2026-01-02 | 30 |
| A | 4 | 2026-01-04 | -20 |
| B | 5 | 2026-01-01 | 40 |
| B | 6 | 2026-01-03 | 60 |
WITH events AS (
    SELECT 'A' AS account_id, 1 AS event_id,
           CAST('2026-01-01' AS DATE) AS event_day, 100 AS amount
    UNION ALL SELECT 'A', 2, CAST('2026-01-02' AS DATE), 50
    UNION ALL SELECT 'A', 3, CAST('2026-01-02' AS DATE), 30
    UNION ALL SELECT 'A', 4, CAST('2026-01-04' AS DATE), -20
    UNION ALL SELECT 'B', 5, CAST('2026-01-01' AS DATE), 40
    UNION ALL SELECT 'B', 6, CAST('2026-01-03' AS DATE), 60
)
SELECT account_id, event_id, event_day, amount,
       SUM(amount) OVER (
           PARTITION BY account_id
           ORDER BY event_day, event_id
           ROWS BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW
       ) AS running_amount
FROM events
ORDER BY account_id, event_day, event_id;
Account A receives 100, 150, 180 and 160. Account B receives 40 and 100. The second account starts its own calculation because it forms a separate partition. The negative correction reduces the running total. The word “running” does not promise that the numeric result always increases.
The WITH block is a common table expression, available within this statement. In subsequent fragments, events means the same dataset. Add the block again to run a fragment independently. This example does not create a permanent table or define a complete accounting process.
Date ties: why a date alone is insufficient
Account A has two events on January 2. If you order only by date and use ROWS, one position precedes the other, but the query does not uniquely specify which. The amount 50 can come before 30 or after it. The total at the end of that date is 180 either way.
The intermediate result attached to a particular event differs. Under our explicit order, event two receives 150 and event three receives 180. Reversing the two tied positions could give event three an intermediate result of 130 instead. I do not want an event-level balance report to depend on an incidental technical ordering.
That is why I added event_id. It is a deliberate rule in this synthetic example. In a real system, establish whether the identifier reflects the intended ordering. A random identifier can make an answer reproducible without proving the actual chronology of events that arrived late or were imported in batches.
RANGE and the default frame
In MySQL 8.4, omitting the frame when ORDER BY is present gives RANGE BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW. RANGE includes peers according to the window ordering. With event_day alone, the two January 2 events are peers.
SELECT event_id, event_day, amount,
       SUM(amount) OVER (
           PARTITION BY account_id
           ORDER BY event_day
           RANGE BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW
       ) AS total_through_day
FROM events
WHERE account_id = 'A'
ORDER BY event_day, event_id;
The results for A are 100, 180, 180 and 160. Both January 2 positions show the total through that entire date. This is a sensible answer if that is how you defined the report. A small dataset makes the distinction from ROWS visible without random data or a large database.
Adding event_id to this window would change the peer definition. Do not compare ROWS and RANGE while also changing the ordering columns, then attribute the entire difference to the frame alone. During an investigation, I change one element at a time and write down what each output column is intended to mean.
ORDER BY inside the window and at the end
Ordering inside OVER serves the calculation. The final ORDER BY serves presentation. I included both because I want to calculate by date and identifier and display the result in the same order. These are two explicit decisions that happen to agree in this example.
I can display events descending while keeping a running total calculated ascending. The newest A row would then show 160 at the top. That does not mean the total was calculated backward. Someone reading the report needs to understand the balance attached to each event rather than infer its meaning from screen position.
Changing the direction inside OVER changes which positions count as preceding. That affects the calculation itself. When improving a report’s appearance, I therefore do not blindly move its final sorting into the window definition. Presentation order and accumulation direction may serve different needs.
The last rows are different from the last days
ROWS BETWEEN 1 PRECEDING AND CURRENT ROW includes the current position and up to one preceding position. For A, its sums are 100, 150, 80 and 10. The first position has only itself. The third includes 50 and 30; the fourth includes 30 and -20.
These are the last two events, rather than the last two days. There is a gap between January 2 and January 4, while January 2 has two events. A report about calendar days first needs the right data grain and a policy for dates with no events.
For daily running totals, I can first group by account and date. Account A then has daily amounts of 100, 80 and -20, with cumulative results of 100, 180 and 160. I have avoided treating two different events as though they represented two different days.
A seven-day average requires another decision about empty days. The average over active dates can differ from the average over all calendar dates. A calendar row with no event is also different from an event with an unknown amount. I establish the denominator before choosing the frame.
A filter can change the starting point
MySQL window functions operate on the rows remaining after WHERE, GROUP BY and HAVING. Filtering away the beginning of history at the same query level removes it from the calculation. Limiting the visible records must be distinguished from limiting the input to the running total.
For account A, filtering event_day >= '2026-01-04' before windowing leaves only the -20 correction. The total for that date becomes -20. If I calculate the full history in a CTE first and then display January 4, I get 160. Both results follow logically from different questions.
WITH calculated AS (
    SELECT account_id, event_id, event_day, amount,
           SUM(amount) OVER (
               PARTITION BY account_id
               ORDER BY event_day, event_id
               ROWS BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW
           ) AS running_amount
    FROM events
)
SELECT *
FROM calculated
WHERE event_day >= '2026-01-04'
ORDER BY account_id, event_day, event_id;
This fragment assumes the described events source is available. You can place its CTE before calculated in the same WITH clause. Do not try to reference a window result alias in the WHERE of that same SELECT. A separate level makes the distinction between calculation and display explicit.
A sum of movements is not automatically a balance
Our example starts from zero. A real balance can require an opening value from before the available history. If the database contains November movements only, their sum does not reveal the balance at the end of October. A perfectly specified frame cannot reconstruct an input that is missing.
I would establish the opening amount, movement period and correction policy separately. Does a correction revise a historical date, or become a new movement on its posting date? Those choices produce different cumulative paths. A column called balance should follow an agreed definition, especially when it is reconciled against another source.
Units matter as well. Do not add different currencies or combine item quantities with sales amounts inside one series. PARTITION BY can help separate series, but you first need every dimension that makes summing meaningful. One technical account column does not necessarily represent a coherent series by itself.
Consider a late import too. Adding an event tomorrow with an earlier event date can change subsequent states when history is recalculated. That is an expected consequence of new input, although an earlier exported file showed different numbers. When comparing exports, I record the data retrieval time and available history. Stable ordering alone does not guarantee identical results for two different source snapshots. Explain a discrepancy through the missing event or correction policy before treating it as a window-function mistake.
Missing values, whole partitions and LAST_VALUE
MySQL SUM ignores NULL and returns NULL when there are no values to sum. Automatically replacing an unknown amount with zero can make an incomplete total look complete. For a quality report, I would include a missing-value count instead of hiding the issue behind a convenient number.
To show the entire partition total beside each event, SUM(amount) OVER (PARTITION BY account_id) is enough. If explicitly specifying a whole-partition frame, its end is UNBOUNDED FOLLOWING. This answers a question about the account total in the selected input, without accumulating step by step.
Be careful with LAST_VALUE: it refers to the last position of the frame. With a frame ending at the current row, that need not be the account’s final event. MySQL also ignores the frame for functions including ROW_NUMBER and LAG. Function names do not establish identical boundary behavior.
When the calculation should restart
A partition’s starting point is part of the metric definition. Account A currently has one continuous history. If a report should show movements accumulating separately within each month, the partitioning needs a month boundary. Displaying a month name beside the result does not reset anything. It remains a descriptive attribute until an appropriate calculation rule uses it.
I would not use a month number alone to identify reporting periods. January in one year and January in another year are separate periods. First I would prepare an unambiguous month key containing the year, then separate the series by account and that key. This avoids silently combining events a year apart into the same accumulation.
Distinguish sales since the start of the month from the current account balance. The first measure naturally begins a new period. The second may need an opening balance carried forward. When both appear on a dashboard, give them different names and explain their scope. A reader should not have to guess why one total starts from zero while another starts from a previous balance.
Imagine adding an event in February. A whole-history running total adds it to the January result. A monthly running total treats it as the first contribution to a new partition. You can describe both predictions before writing SQL. If nobody knows which is expected, the report definition needs clarification before choosing another window expression.
Order lines and the correct row unit
The same mechanism can accumulate quantities across the lines of an order. Order identifier is then a natural partition candidate, with item quantity as the measure. Ordering still needs a decision. Product identifier does not necessarily identify a line uniquely: one product can occur twice, perhaps with different discounts or delivery dates.
For that report, I would first identify a line key or an explicit sequence number. Then I would decide whether the reader needs the order-entry sequence, warehouse picking sequence or presentation sequence on a document. Each can be valid, but each gives a different meaning to “through this line.” Alphabetical product ordering does not automatically describe fulfillment history.
Keeping the same row count through a window function can make different measures easy to confuse. Three line items can have three cumulative quantities beside them. Summing that new column later repeatedly counts earlier contributions. For account A, adding the states 100, 150, 180 and 160 does not give the total value of the events. A final state and the sum of intermediate states answer different questions.
That is why I describe the exported column as a value at a particular stage. For later aggregation, I return to event amounts or select the appropriate closing state for each series. I would not blindly choose the largest balance: after a negative correction, the maximum can belong to an earlier moment while the closing value is smaller.
How I read a more complicated query
When reading someone else’s code, I start with the input to the function. I write down what a row represents after joins and grouping. Next I inspect the partition, direction and extra ordering criteria. Only then do I read the frame boundaries. This avoids comparing ROWS variants while the real problem is a duplicated order line earlier in the query.
Next I write out one short series manually. For each position, I mark which values enter or leave the frame and which contribute to the sum. A small dataset is enough to reveal that a filter removed an earlier contribution or that tied events lack a defined sequence. A long output can make a simple relationship harder to see.
For a larger dataset, I separate the correctness of the definition from execution cost. An explicit frame does not guarantee a fast report, and speed does not confirm the intended business meaning. First I compare understandable cases and expected results. Then I inspect how the actual data is processed. I do not promise a universal speed improvement from adding an index without understanding the whole query.
Exercise and report checks
Add event seven to account A on January 5, with amount 10. Predict the final running total: 170. Then calculate the sum of the last two events: -10. Write down which rows contribute to each answer. If the explanation relies only on a function name, return to the data.
Before delivering the report, inspect the first position in each partition, two events with the same date and one negative correction. Check the beginning-of-period filter too. These small cases expose different mistakes: missing partitioning, ambiguous ordering, an unsuitable frame and history removed before calculation.
If windowing follows a JOIN, also check that the join has not duplicated events. The frame sums the rows it receives, so repeated input makes a repeated contribution. Revisit LEFT JOIN and row counts and SQL clause order. Assess the running result only once the input represents the intended events.
Key takeaways
What does ROWS UNBOUNDED PRECEDING mean?
The frame includes positions from the start of the current partition through the current row. Its full form ends with AND CURRENT ROW.
Is ROWS the default frame when ORDER BY is present?
MySQL 8.4 defaults to RANGE BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW. It includes peers according to the window ordering expressions.
Does ROWS 6 PRECEDING mean the last seven days?
It includes the current row and up to six preceding rows. Rows represent days only after you prepare an appropriate complete daily series.
AI was used in an automated way while working on this article. If you want to learn how to do it too, check out this project.