KajoData / SQL
SQL LEFT JOIN: unmatched rows, counts and totals
I show why three customers produce four rows, how unmatched customers remain visible and why order counts need a non-null key.
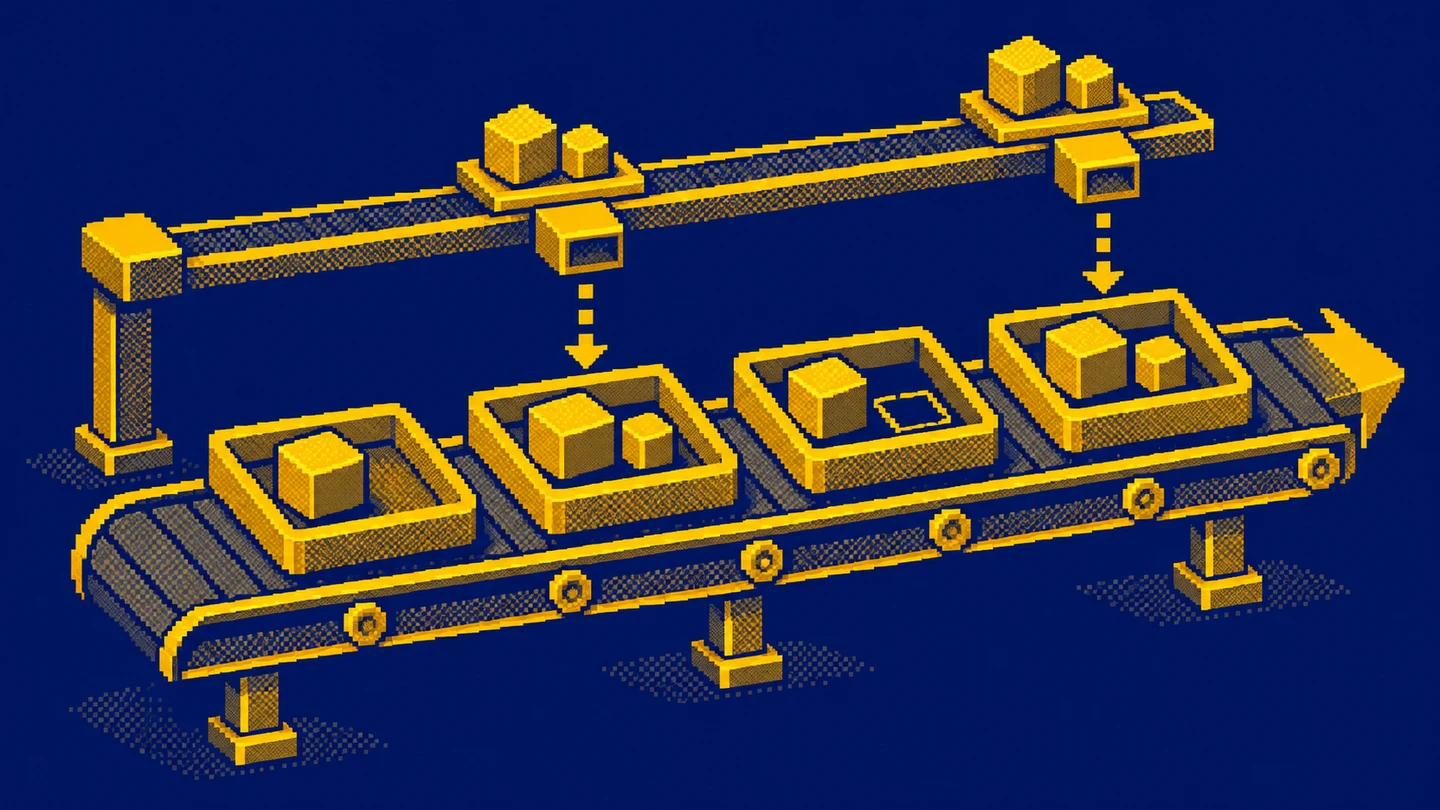
You have a customer list and want to add orders to it. You choose LEFT JOIN because customers without purchases should remain visible. Then three customers turn into four result rows. Has the query gone wrong? Perhaps one customer simply placed two orders.
I start this kind of analysis by deciding what a result row should represent. Only then do I choose columns and add amounts. I will show the approach using small synthetic data that you can read in full. The examples use PostgreSQL 18, and amounts are arbitrary units. You can understand every resulting record without access to a company database.
What LEFT JOIN preserves
LEFT JOIN combines two sources according to an ON condition. For each left row, it returns every matching right row. When no right row matches, it produces one row with NULL values in the right columns. OUTER is optional, so LEFT JOIN and LEFT OUTER JOIN name the same operation. This is the definition in the PostgreSQL join documentation.
Preserving left rows does not mean preserving their count. A customer with five matching orders produces five customer and order pairs. A customer without an order produces one row with an empty order side. You need to understand the relationship before predicting the result size.
The guarantee applies to the join itself. A subsequent WHERE, grouping operation or DISTINCT can change the result. The statement that LEFT JOIN always keeps every customer therefore needs a qualification: after the join, before further operations. I will show a filter that removes unmatched customers shortly.
Choose the population you want to keep
Our customers source contains three customers. Each identifier appears once. The name is a display attribute; the identifier establishes the relationship.
| customer_id | customer_name |
|---|---|
| 1 | Ada |
| 2 | Ben |
| 3 | Celina |
The orders source contains three orders. Ada has two, Ben has one and Celina has none. Every actual order has its own non-null identifier.
| order_id | customer_id | amount | status |
|---|---|---|---|
| 101 | 1 | 100 | completed |
| 102 | 1 | 50 | pending |
| 103 | 2 | 80 | completed |
The question is to show all customers together with their available orders. I therefore put customers on the left. Starting from orders and attaching customers would preserve the order population instead. That would answer a different question, particularly when relationships are missing in the source data.
For a real report, I would also define the customer population. Does it include every historical customer, customers active today or one particular segment? LEFT JOIN cannot decide that definition for you. It preserves the source you provide. Customers removed by an earlier filter will not reappear because you picked a particular join type.
Prepare a small practice dataset
The following statement builds two named sources with WITH and VALUES. It does not create permanent tables. Later examples assume the same sources; if you use this statement, retain the WITH section and replace its final SELECT. CTE names are available within a single statement.
WITH customers(customer_id, customer_name) AS (
    VALUES (1, 'Ada'), (2, 'Ben'), (3, 'Celina')
), orders(order_id, customer_id, amount, status) AS (
    VALUES
        (101, 1, 100, 'completed'),
        (102, 1, 50, 'pending'),
        (103, 2, 80, 'completed')
)
SELECT c.customer_id, c.customer_name, o.order_id, o.amount
FROM customers AS c
LEFT JOIN orders AS o ON o.customer_id = c.customer_id
ORDER BY c.customer_id, o.order_id;
The VALUES documentation describes this way of supplying rows. I use it to make the assumptions visible. You do not need to guess which records sit outside a screenshot or whether an additional source filter exists.
The aliases c and o shorten references. The prefix tells me which source provides customer_id. Both sources contain a column with that name, so specifying the side avoids ambiguity. An alias changes neither the data nor the matching rule. It simply makes a longer query easier to follow.
Read the four output rows
| customer_id | customer_name | order_id | amount |
|---|---|---|---|
| 1 | Ada | 101 | 100 |
| 1 | Ada | 102 | 50 |
| 2 | Ben | 103 | 80 |
| 3 | Celina | NULL | NULL |
Ada appears twice because two orders satisfy the ON condition. Ben appears once. Nothing matches Celina, so PostgreSQL supplies NULL values on the right. The result has four rows while still covering all three customers.
A row now represents a customer and order pair, or a customer without a match. It does not simply represent one customer. Counting the rows and calling that number the customer count would produce four instead of three. The error would be in the interpretation of the result grain.
I added ORDER BY so the output has an explicit presentation order. A JOIN alone does not promise row order. Seeing the same arrangement through several refreshes does not establish a guarantee. The sorting documentation identifies ORDER BY as the way to guarantee output ordering.
A condition in ON defines eligible matches
Suppose I only want completed orders but still need every customer. I add the status condition to the join condition.
SELECT c.customer_id, o.order_id
FROM customers AS c
LEFT JOIN orders AS o
    ON o.customer_id = c.customer_id
    AND o.status = 'completed'
ORDER BY c.customer_id, o.order_id;
The result contains 1, 101, 2, 103 and 3, NULL. Order 102 fails the status condition and is therefore ineligible as a match. Celina remains. If Ada only had a pending order, she would also remain with NULL on the order side.
The placement expresses a specific requirement: the condition defines qualifying relationships. A customer without a completed order must remain visible. That does not necessarily mean the customer has never ordered anything. They might have an order with another status, outside the definition used by this report.
Moving the condition to WHERE changes the question
SELECT c.customer_id, o.order_id
FROM customers AS c
LEFT JOIN orders AS o ON o.customer_id = c.customer_id
WHERE o.status = 'completed'
ORDER BY c.customer_id, o.order_id;
This returns only 1, 101 and 2, 103. After the join, Celina has NULL in the status column. Comparing that value with completed does not produce true, so WHERE removes the row. The WHERE section of the documentation also illustrates the difference between filtering matches and filtering a joined result.
I would not automatically repair this with OR o.order_id IS NULL. A customer with only a pending order has a genuine match. The join does not create an additional empty row for that customer, so the proposed condition still removes them. Put the status condition in ON when the requirement is all customers and completed orders only.
This is a useful moment to revisit the business wording. Customers with a completed purchase and all customers with information about completed purchases sound similar. They describe different populations. I prefer resolving that difference before turning the result into a chart.
Find customers without orders
SELECT c.customer_id, c.customer_name
FROM customers AS c
LEFT JOIN orders AS o ON o.customer_id = c.customer_id
WHERE o.order_id IS NULL
ORDER BY c.customer_id;
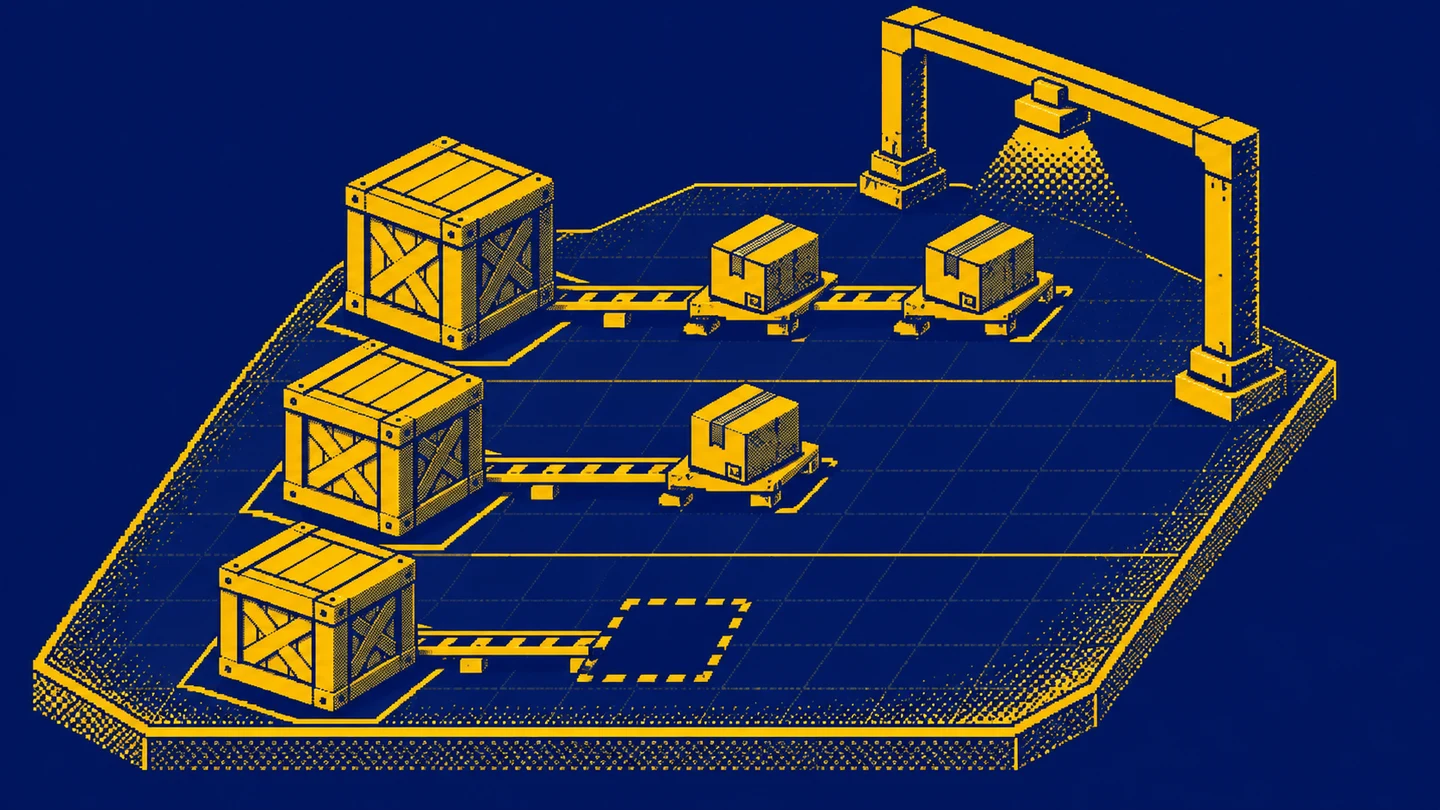
Only Celina remains in our dataset. I test order_id because every genuine order has that identifier. Testing amount IS NULL could confuse an absent order with an existing order whose amount is unknown. Those are different data quality situations and may need different follow-up actions.
In a production database, the primary key of the right table is often an appropriate field. The constraint documentation explains that a primary key requires uniqueness and excludes NULL. I do not assume the same guarantee for an imported CSV column merely because somebody named it id.
NOT EXISTS is another way to express absence. It is especially useful when you only need to know whether a relationship exists and do not need the order columns. The subquery guide develops that choice with explicit examples.
COUNT star and COUNT of an identifier
I now want one row per customer with an order count. I group by the identifier and name, then count non-null order identifiers.
SELECT
    c.customer_id,
    c.customer_name,
    COUNT(o.order_id) AS order_count
FROM customers AS c
LEFT JOIN orders AS o ON o.customer_id = c.customer_id
GROUP BY c.customer_id, c.customer_name
ORDER BY c.customer_id;
The results are Ada 2, Ben 1 and Celina 0. COUNT with an expression ignores NULL. COUNT(*) counts every joined row, so it would return 1 for Celina. That row represents an unmatched customer rather than an actual order. Both forms are described in the aggregate function documentation.
A related distinction appears with totals. SUM returns NULL for Celina because no non-null amounts are available to add. You may define a customer without orders as having zero turnover, but make that decision explicit. Existing orders with missing amounts need a separate completeness check. Replacing every missing total with zero can hide that second situation.
Aggregate before attaching another relationship
Imagine a separate customer contact source. Ada has two orders and two contact numbers. Joining both collections directly through the customer pairs each order with each contact. The two orders now form four combinations.
The amounts 100 and 50 each appear twice. Their sum rises from 150 to 300 even though no purchase has been added. LEFT JOIN preserves rows but provides no protection against this multiplication. Switching to INNER JOIN does not solve it either. You need compatible levels of detail.
If the report should show customers and their turnover, aggregate orders to the customer level first. Bring contacts to a defined shape too, perhaps one selected address under an explicit rule. Then combine those results. Naming a field the main contact does not choose the correct underlying record.
I do not use SUM(DISTINCT amount) as a general repair. Two separate orders can have identical amounts. Removing repeated amount values would then remove legitimate turnover. The order key establishes event identity; the price does not. A clean-looking total can still be a wrong total.
Check what the join key means
Matching column names do not prove matching meaning. A customer number from two independent systems may identify different people. A surname is not a safe substitute for an identifier either. Two people can share a name, and one person can change how their name is recorded.
A source containing customer history needs another rule. The same identifier may appear several times because each row represents a different period. Attaching the entire history to a current order can multiply records. Decide which period should correspond to the event date before writing the relationship condition.
I also check the type and interpretation of the key. A text code containing leading zeros may mean something different from a number. Adding zeros during display does not restore information already lost from the source. Agree on an identifier mapping rule before the join rather than burying an accidental conversion inside it.
NULL on either side of the relationship
With ordinary equality, NULL does not match NULL. An unknown customer key and an unknown order customer key do not establish that the records belong together. Connecting every missing key could create many false relationships.
That is why I do not replace missing identifiers with a shared zero before joining. Doing so would assign one identity to different unknown objects. If the data cannot establish a relationship, the result should retain that uncertainty. It tells you something useful about the quality and limits of the source.
I also distinguish a NULL stored in a genuine order from a NULL supplied by the outer join. A non-null right-side identifier makes this distinction possible. An empty product description or a missing price alone is insufficient evidence that no order exists.
Build one customer row before another join
Here I aggregate orders to the customer level in a separate subquery. The customers and orders sources remain the same. When using the earlier WITH section, replace its final SELECT with this query.
SELECT
    c.customer_id,
    s.order_count,
    s.total_amount
FROM customers AS c
LEFT JOIN (
    SELECT
        customer_id,
        COUNT(*) AS order_count,
        SUM(amount) AS total_amount
    FROM orders
    GROUP BY customer_id
) AS s ON s.customer_id = c.customer_id
ORDER BY c.customer_id;
The subquery produces one row for Ada with count two and total 150, and one for Ben with count one and total 80. It produces no row for Celina because the order source contains none of her orders. After joining, Celina therefore has NULL in both summary columns. This differs from counting order identifiers after the outer join.
If you need zero, use COALESCE(s.order_count, 0) in the outer SELECT. At this point, an absent summary row means no orders exist. For the amount, keep a separate check for existing orders with unknown values. The total column alone cannot establish that distinction.
The subquery has an explicit contract: at most one row per customer identifier. Joining it to a unique customer list does not multiply that list. Attaching multiple contacts afterwards would change the grain again. Every additional join needs its own assessment.
RIGHT JOIN preserves the opposite side of the relationship. Swapping the sources usually lets me express the same question with LEFT JOIN. I choose the version whose intention is easiest to read, without assuming the wording alone determines performance.
Empty sources and execution plans
If the order source is empty, joining the three customers to it still produces three rows with NULL on the right. If the customer source on the left is empty, the result is empty even when the right source contains orders. These cases are useful checks of which population the query preserves.
My manual explanation follows customers and their matches to make the result easy to derive. PostgreSQL can choose a different physical algorithm. The EXPLAIN documentation describes how to inspect that plan. I make no general claim that changing LEFT JOIN to INNER JOIN improves performance. It may change the required population instead.
Exercise: every customer, completed purchases only
Change the COUNT query to count only orders with status completed while retaining all customers. First write down the expected result manually. Ada has one completed purchase, Ben has one and Celina has zero. Then place the status condition in ON and count order_id.
Add a synthetic customer named Dan with one pending order. Dan should also have zero completed purchases and remain visible. This case distinguishes the correct ON condition from a WHERE filter with an added NULL check that only seems to solve the problem.
Finally, describe a result row in a full sentence. State which customer population is preserved, which orders qualify and why an absent match produces a zero count. If you can explain those points, you understand the report beyond its syntax. Continue with INNER JOIN and the COUNT reference.
Review the result before sharing it
I compare the distinct customer identifiers in the report with the intended starting population. Then I inspect one customer with several orders and one without orders. Those two cases reveal more than checking a handful of populated rows at the top of the output.
I also read the column labels from the recipient’s perspective. A field called orders should make clear whether pending purchases are included. A total should say what unit and period it covers. SQL can assemble the rows correctly while the report still invites the wrong interpretation. The final explanation is part of the analysis.
Key takeaways
Does LEFT JOIN preserve the left table row count?
It preserves every left row, but multiple matches create multiple result rows. A later WHERE can remove rows again.
Where should I filter right-side rows while keeping all customers?
Put the condition in ON when it defines eligible order matches. WHERE filters the joined result and can remove unmatched customers.
Why does COUNT(*) return one for a customer without orders?
LEFT JOIN produces one row with NULL on the order side. Counting a non-null order identifier returns zero for that customer.
AI was used in an automated way while working on this article. If you want to learn how to do it too, check out this project.