KajoData / python en
Text to a Python list: lines, words and empty fields
Choose lines or words as list items, preserve meaningful whitespace and recognise when a CSV reader is the right tool.
You want to turn a text file into a Python list. Before I add .split(), I decide what one item should represent: a complete line, an individual word, or a field separated by a semicolon. That choice determines which information survives the import.
The examples below use Python 3.14 and small synthetic inputs. Expected results follow the documented rules. Your own file also needs a known encoding and a clear description of its structure.
Keep each line as one list item
Suppose notes.txt is a UTF-8 file with these three lines:
Converting
text to list
in Python
I want three items, including one containing the complete phrase text to list. For a small file, I use:
from pathlib import Path

text = Path("notes.txt").read_text(encoding="utf-8")
lines = text.splitlines()
The expected contents of lines are:
['Converting', 'text to list', 'in Python']Path.read_text() reads the file and closes it afterwards. splitlines() separates the text at line boundaries, leaving out line endings by default. Words within a line stay together. That is the data shape I want here.
A relative path starts at the program’s current working directory. If Python raises FileNotFoundError, I first check where the file actually lives. Another call to split() will not fix a directory problem.
split, splitlines and list do different jobs
These expressions answer different questions:
| Expression | One resulting item | Typical purpose |
|---|---|---|
text.splitlines() |
A line | Descriptions or records stored one per line |
text.split() |
A piece between whitespace | Simple word splitting |
text.split(";") |
A piece between semicolons | Plain text with a known delimiter |
list(text) |
One Unicode code point | Working with characters |
For the synthetic string "red blue\ngreen", split() produces three items: red, blue, and green. splitlines() produces two: red blue and green. list() also turns the space and newline into individual items.
The str documentation explains the splitting rules. For analysis, I start with the meaning of a record. If an item represents a customer’s comment, splitting it into separate words will make it harder to keep that comment attached to its original record.
Read line by line with with open
When I want to make the iteration explicit, I use a context manager:
lines = []

with open("notes.txt", "r", encoding="utf-8") as source:
    for line in source:
        lines.append(line.rstrip("\n"))
With the normal text-mode settings, open() translates standard line endings into \n. Here I remove that trailing character while retaining other spaces. The with block closes the file even if an exception occurs inside it. Python’s file reading tutorial describes this behaviour.
This approach still builds the entire list in memory. A loop does not make an arbitrarily large input cheap to load. If the task only needs a line count or one record processed at a time, I can do that work inside the loop without storing every line.
A list comprehension gives a shorter form:
with open("notes.txt", encoding="utf-8") as source:
    lines = [line.rstrip("\n") for line in source]
I use it when the individual transformation remains easy to read. Once record rejection rules, error messages and several conditions enter the picture, a normal loop often makes the reasoning clearer.
strip can remove useful information
Without an argument, strip() removes whitespace from both ends of a string. That includes spaces and tabs as well as line endings. Applied to " red \n", it produces "red". Any meaningful indentation is now gone.
Before cleaning the text, I decide whether those spaces are decoration or part of the value. They can matter in a product identifier, fixed-width export or code fragment. Removing them from a hand-written city list may be useful, but it remains a decision about the data.
I also avoid using strip(".txt") to remove a file extension. The argument describes a set of characters to remove from the ends, rather than a complete suffix. That distinction is easy to miss because a single convenient example can appear to work.
Build a list of lists for words within each line
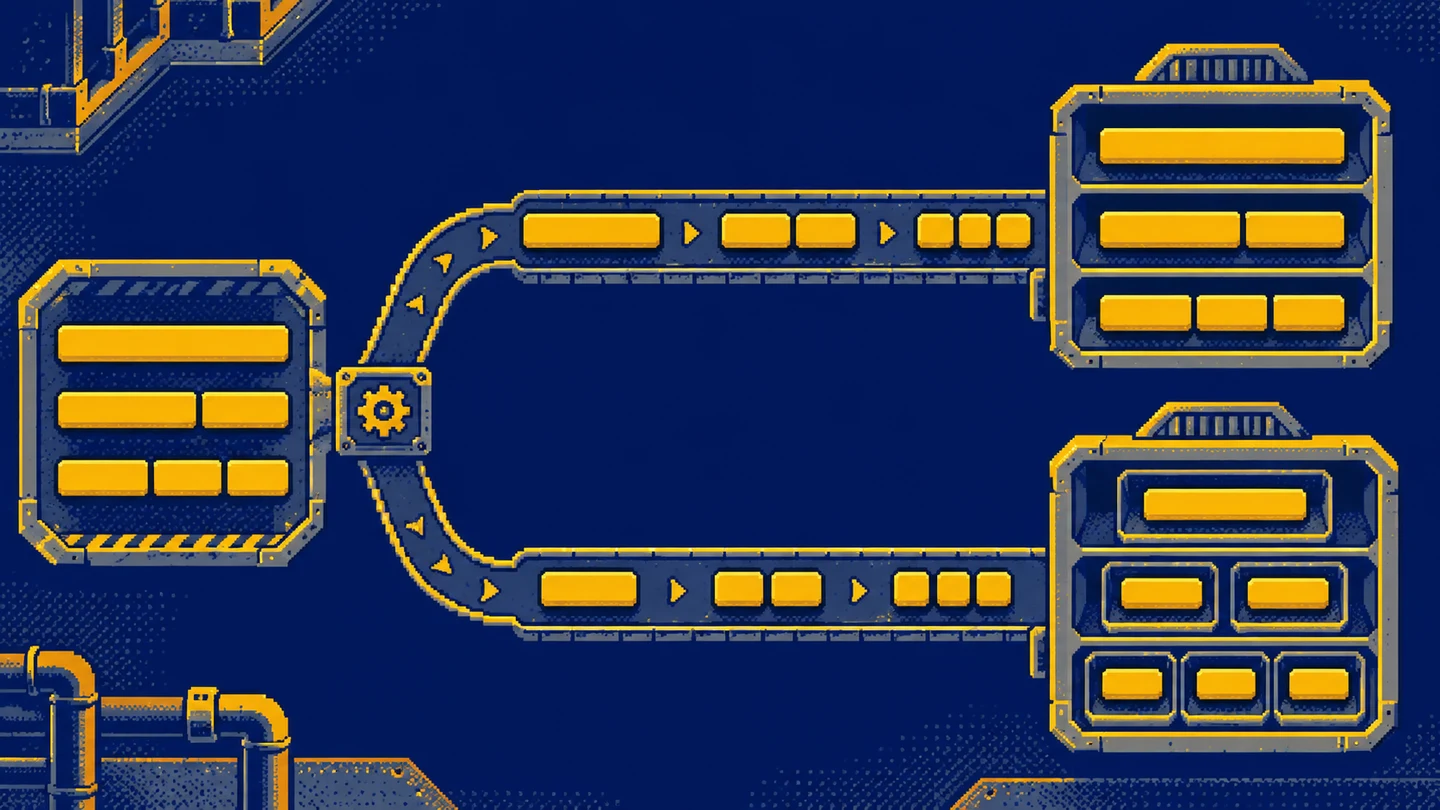
Return to the three-line file. This time I want to preserve line boundaries and split each line into words:
with open("notes.txt", encoding="utf-8") as source:
    rows = [line.split() for line in source]
The expected contents are:
[['Converting'], ['text', 'to', 'list'], ['in', 'Python']]The outer list represents lines. Inner lists have different lengths because the lines contain different numbers of words. I therefore cannot assume that each inner list has an item at index 2. The second line does, while the first one does not.
Adding strip() before a separator-free split() is unnecessary here. This form of splitting already ignores surrounding whitespace and groups consecutive whitespace together. Keeping only the operation I need makes the transformation easier to explain.
Decide what empty lines and fields mean
The synthetic string "red\n\nblue\n" becomes ['red', '', 'blue'] with splitlines(). An empty line in the middle remains an item. The final newline does not add another empty item. Empty input produces an empty list.
If the file includes blank lines, [line.split() for line in source] retains them as empty inner lists. That can be helpful when a blank line separates sections. I do not automatically discard it just to make the result look tidier.
An explicit separator changes the behaviour. "red;;blue;".split(";") gives ['red', '', 'blue', '']. Empty fields may represent missing values. Deleting them would move later values into the wrong positions. In a table, that becomes a real data error even though the program still runs.
Use a CSV reader for CSV files
A surname, comment or product name can contain the delimiter itself. Simple comma splitting then stops representing the original columns. For CSV with quoted fields, I use Python’s csv module:
import csv

with open("products.csv", encoding="utf-8", newline="") as source:
    rows = list(csv.reader(source, delimiter=";"))
This example assumes a semicolon delimiter. A header, if present, also becomes a row in the list. Fields are returned as strings here; converting a price or date to an appropriate type is a separate step.
The module documentation recommends newline="". I also avoid guessing the delimiter from the extension alone. A file ending in .csv may come from an application with different export settings.
Check encoding and file size
An explicit encoding="utf-8" states an assumption. It does not repair every possible file. If I get UnicodeDecodeError, I check the export format at its source. Ignoring decoding errors can silently remove part of a product name or identifier, so I do not treat it as a harmless fix.
After reading, I inspect a few known values containing accented characters. The absence of an exception does not prove that the text was decoded as intended. The next processing step matters too: a million-item list uses memory whether I create it in one line or in a loop.
For a broader introduction to working with tabular data, see the first pandas reporting project. Splitting text prepares information for analysis; it does not yet establish that the information is correct.
Exercise: decide what must survive
Make a small file containing two descriptions, a blank line, and a description starting with two spaces. Write down the expected list for two different tasks: retaining the original lines faithfully and producing cleaned, non-empty descriptions.
Choose the operations separately for each task. Check whether the item count, indentation and spaces within descriptions change. Only then shorten the code into a list comprehension. I want a clear expectation for the resulting data first. Compact code is a useful extra.
Key takeaways
How do I turn each file line into a list item?
For a small file, use Path.read_text with an explicit encoding and splitlines. When iterating over a file, use with open and deliberately remove only line endings.
Does strip remove only the newline?
No. Without an argument it removes surrounding whitespace, including spaces and tabs, which can remove meaningful indentation.
Is split enough for reading CSV?
Quoted fields and delimiters within values require a CSV reader such as csv.reader, configured for the actual export.
AI was used in an automated way while working on this article. If you want to learn how to do it too, check out this project.