
KajoData / Career & business
What a data scientist does: from a question to an evaluated model
I work through a fictional late delivery prediction project to show the decisions before training and the responsibilities after a model produces a score.
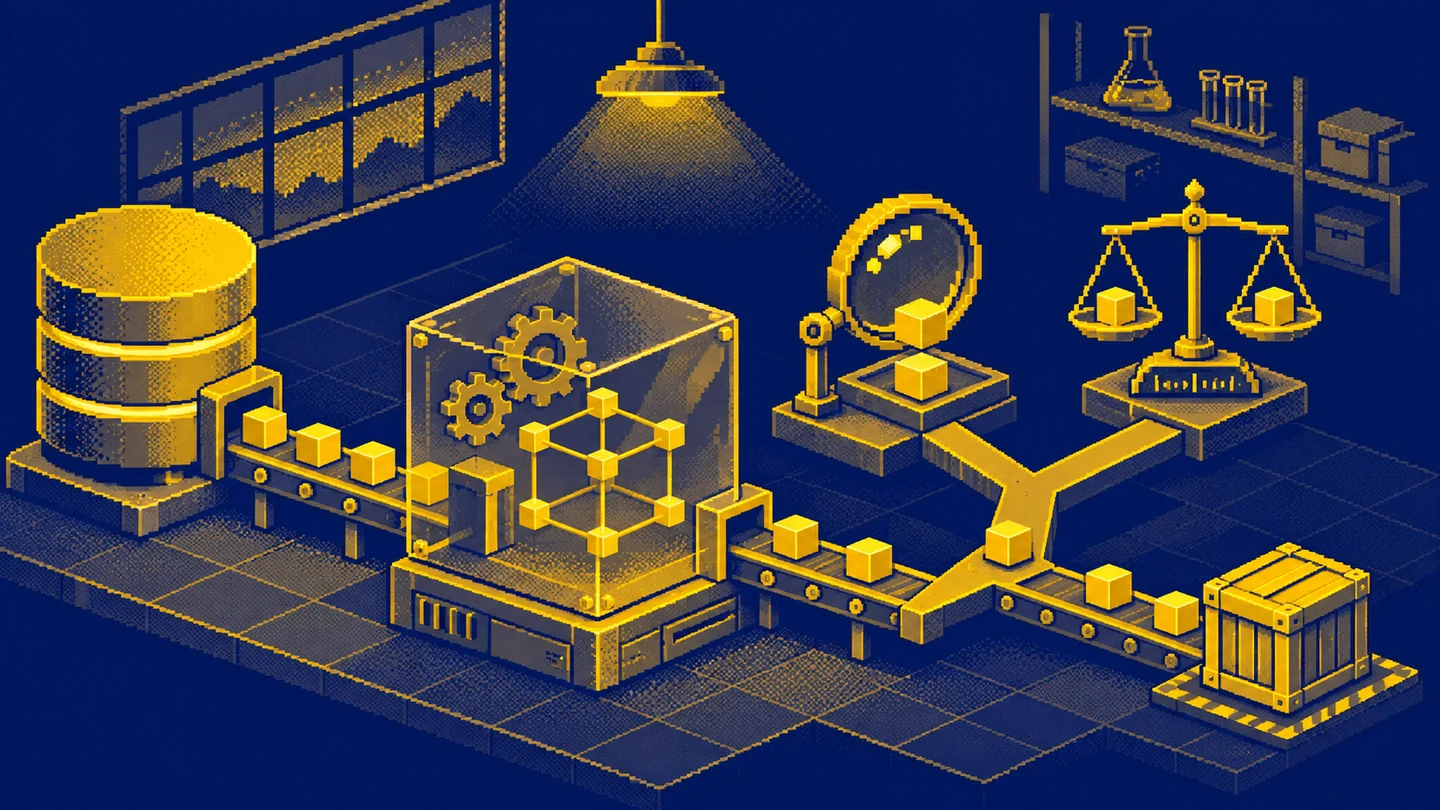
When someone asks what a data scientist does, I would start with the work before choosing an algorithm. We need to agree on the problem, the information available and what would make the result useful. Modelling then becomes a meaningful part of the project. Without that preparation, it is perfectly possible to train an impressive model that answers the wrong question.
Data science combines work with data, statistical methods, programming and an understanding of the application. It can involve exploration and experiments as well as prediction. I would avoid reducing the field to forecasting the future or assuming that every company divides responsibilities in the same way. Several specialists may share a solution, while one person may cover many stages in a smaller team.
Below, I use a synthetic example: identifying parcels at risk of arriving late. This is a learning scenario, with no client results and no claim that an experiment was run. I will focus on decisions that need an explanation. The name of a fashionable library will not make those decisions for us, however good its documentation might be.
What belongs to the role
The BLS occupational description includes selecting and analysing data, creating and evaluating models, presenting findings and making recommendations. It describes duties in the United States. I use it as a broad reference, without treating it as evidence about salaries or hiring conditions in another country. A particular vacancy still needs its own careful reading.
I would separate three project questions. Can we describe the problem? Does a model provide useful information? Can the organisation act on that information? A technically successful project can get stuck on the third question. Predicting a delay does not speed up a parcel by itself. Someone needs an opportunity to investigate the delivery or change what happens next.
Compared with a data analyst position, responsibility for modelling and evaluating generalisation to new observations is more likely to appear. The boundary remains flexible. Analysts can run experiments, and data scientists can prepare simple summaries. I would discuss the balance through the team’s actual projects. A title alone cannot tell you how much time goes into code, meetings or preparing source records.
Start with the action after the prediction
In our example, a manager wants a morning list of parcels to investigate. The team can check ten cases per day. I would ask what happens after a check: can someone contact the carrier, correct an address or only inform the recipient? Each possibility changes the definition of a useful model and the moment when its output would still help.
Google’s guidance on framing an ML problem separates the business goal from a model’s output and evaluation metrics. Here, the output could be a delay risk, while the goal could be earlier action on threatened deliveries. I would record them separately. An improvement in prediction quality cannot automatically be described as an improvement in customer service.
I would also ask whether a model is necessary. If many failures come from a missing address field, a simple rule and a better form may be a sensible first step. Compare those options before expanding the solution. A useful data science recommendation can be to postpone machine learning because the current problem is better addressed with a simpler change.
Define the prediction time and the label
Assume we assess each parcel at eight in the morning on its planned delivery day. A late label means arrival after the promised deadline. We need the historical promise that applied when the assessment was made. If the deadline changed later, using only its final version could silently change the definition of success and hide an earlier problem.
I would avoid automatically marking parcels without a delivery confirmation as on time. First establish whether enough observation time has passed and whether the source has supplied its updates. Training needs resolved outcomes under an agreed rule. An unknown outcome is a separate condition to investigate or deliberately exclude from a particular stage, with its effect on coverage made visible.
Define the unit of observation as well: one parcel at one assessment time. A scan history can contain several rows for the same parcel. Treating them as independent deliveries changes the question answered by both the model and the report. I would want to follow one case from source events to its final label without having to guess how the records were combined.
Collect information available at the right time
Possible inputs include the region, weekday, promised deadline and last known transport stage. For every field, record when it becomes available. The final delivery timestamp helps build a historical label, but it cannot be an input to the morning prediction. At the time of the decision, that timestamp is still unknown. A retrospective table can make that distinction surprisingly easy to miss.
The scikit-learn guidance on data leakage explains the danger of using information unavailable at prediction time. In this example, I would keep morning features separate from later outcomes. I would also inspect when a status reached the system. The time of an event and the time its update was received can differ, which matters when reconstructing an earlier decision.
I would resist collecting every available field simply because another table can be downloaded. Each field needs a reason, adequate quality and a permitted use. Personal recipient details may be unnecessary for this exercise. Start with the smallest set of information needed for a fair comparison with a simple rule. Additional information can then be considered as a deliberate extension rather than an automatic improvement.
Preparing data involves decisions
A missing scan might indicate an integration outage, a skipped stage or a genuine transport problem. I would investigate before replacing it with an arbitrary status. If the causes cannot be distinguished, preserve that uncertainty in the project description. A table with every cell filled is no proof that the source has become more accurate or that the replacement means what we think it means.
Duplicates need similar care. Two parcel updates can be legitimate events, while two copies of the same message need different handling. Before joining tables, define the expected relationships and number of cases. Afterwards, check whether some parcels multiplied because several records matched in another source. Every resulting row can look plausible while the population is already wrong.
Keep enough information to trace changes. I want to know which records were excluded, under what rule and with what effect on coverage. If cleaning mainly removes difficult cases, the reported result describes an easier environment than the one where the solution will operate. Make that limitation explicit before evaluating usefulness, rather than leaving it for someone else to discover after deployment.
Compare with a simple baseline
Imagine one hundred parcels: ninety arrive on time and ten arrive late. A rule predicting that every parcel will be on time makes ninety correct predictions. Its accuracy is 90%, although it identifies none of the threatened deliveries. A high score by itself therefore tells us very little about whether the morning investigation list will help the team.
DummyClassifier in scikit-learn provides simple reference strategies. In our scenario, I would also compare against an explicit operational rule, such as investigating parcels without an expected scan. Use the same period, population and daily checking capacity for both methods. Otherwise, an apparent improvement may come from a different comparison rather than a better solution.
I would begin with a method whose mistakes I can inspect and explain. Greater complexity may be justified, but it needs to provide a useful improvement over the reference. Counting model layers is a poor way to assess a practical project. I would rather see where the method helps, where it fails and what the comparison allows us to conclude about those differences.
Evaluate on data not used for fitting
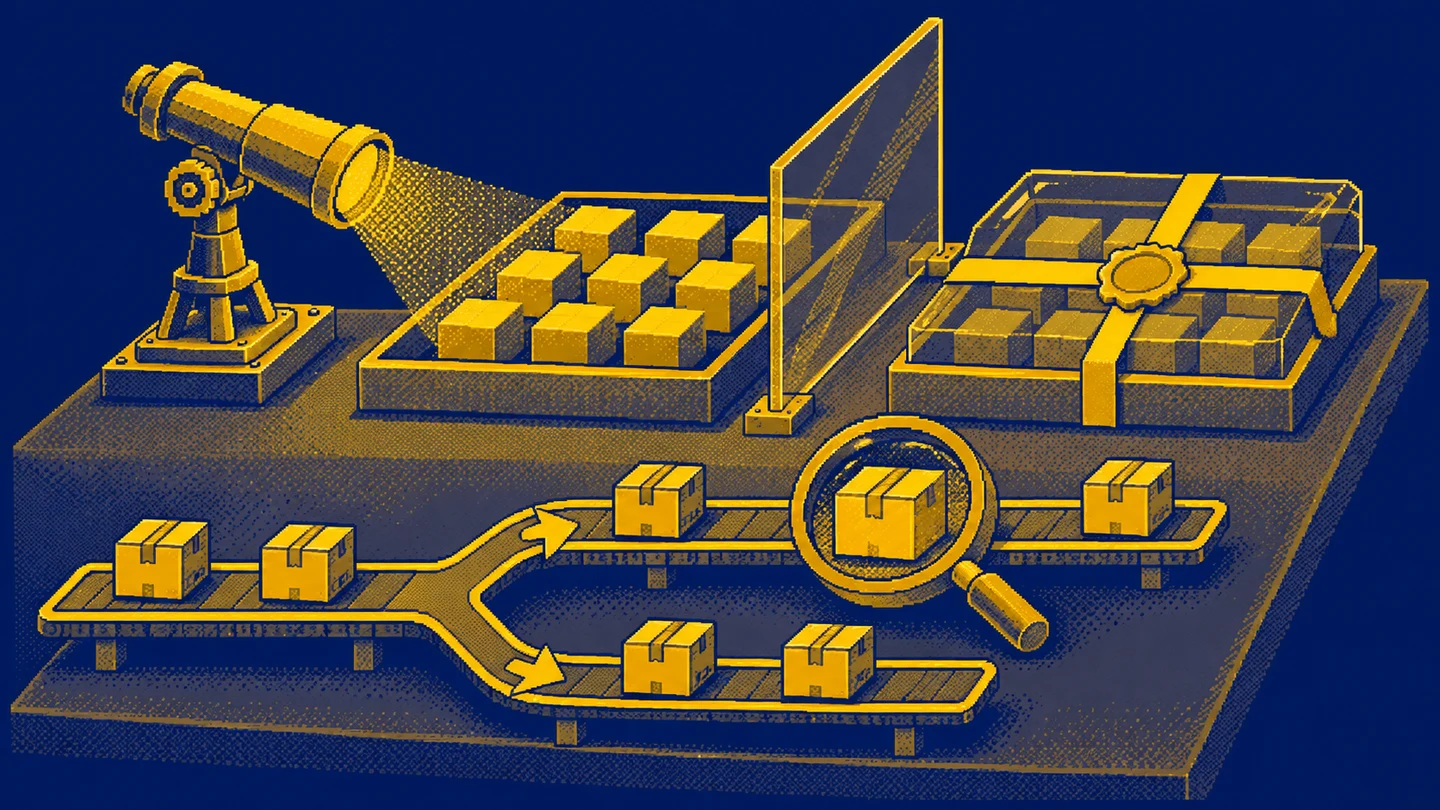
A model can reproduce familiar examples very well and perform poorly on new ones. The scikit-learn cross-validation guide explains separating evaluation from training and respecting temporal structure. For our example, I would propose learning from earlier deliveries and evaluating on a later unused period, with the design matched to how predictions would actually be made.
Choose dates so that each training outcome would already have been known at the historical training time. Also check that repeated observations of the same parcel do not enter both parts. We want to reconstruct future working conditions. Giving the model another view of a case it has already encountered can make the exercise easier without making the actual solution more useful.
After many revisions against the same evaluation set, that set becomes part of model selection. I would reserve final material for a later independent check before announcing performance. A small sample can still produce an unstable estimate. State its size and scope rather than presenting one percentage as a permanent property of the model in every period and for every group.
Different mistakes have different consequences
Consider another synthetic summary. Of ten flagged parcels, six actually arrived late and four arrived on time. There were eight late parcels in the full evaluated group. The model detected six of those eight and missed two. These small counts let us ask two distinct questions about the quality of the investigation list without needing complicated calculations.
Precision is the share of flags that were correct: six out of ten, or 60%. Recall is the share of late parcels detected: six out of eight, or 75%. The denominators differ. Neither number tells us the cost of a check or the value of acting earlier on a particular threatened parcel.
I would discuss those consequences with the user. An unnecessary check takes time; a missed warning may remove the opportunity to intervene. The limit of ten checks also constrains the process. A decision threshold can change which parcels are flagged, but I would evaluate that choice alongside the team’s capacity. Maximising one metric in isolation does not settle the operational decision.
A prediction does not establish an intervention effect
Suppose a flagged parcel would arrive late without contacting the carrier. A historical prediction does not show whether a phone call would prevent the delay. The model provides information about risk. Assessing an action requires its own comparison design and a record of which cases actually received the intervention. I would keep those questions separate when explaining what the project has established.
For a pilot, agree how actions and their timing will be recorded. Establish who selects cases and why. If the team investigates only easy cases, a direct comparison between investigated and uninvestigated parcels may be misleading. A claim about impact needs an evaluation design suited to that situation. The original predictive score cannot supply that evidence on its own.
For a learning project, drawing the boundary clearly is already useful: we have a proposed risk list, rather than proof of deliveries saved. I prefer that honest result to an impressive savings claim that nobody can reconstruct. The reader should understand which part has been assessed and what question remains open before deciding whether the next project stage is justified.
Deployment needs an owner and a fallback
The list needs to reach the appropriate person at the appropriate time. Agree an owner, an update deadline and behaviour when data is missing. If the morning import fails, yesterday’s list should not look current. I would make its last update visible and state the conditions for use. The reader should be able to recognise an unusable result without investigating the pipeline personally.
Google’s monitoring guidance covers checks on inputs and system behaviour after deployment. Here, I would propose watching for missing scans, new categories and changes in parcel volumes. Later outcomes need separate observation once delivery confirmations arrive. An absence of technical exceptions does not prove that the risk list remains useful for the team.
Responsibilities also need agreement. A data scientist may develop the model, a data engineer supply its inputs, and an ML or platform team operate the execution. Smaller organisations may combine those duties. Before accepting the work, I would ask who handles failures and who authorises changes to the rule. Calling a process automated leaves those questions unanswered unless someone explicitly owns them.
Inspect mistakes in relevant groups
A result for the whole population can hide weakness in a meaningful slice. Suppose most parcels come from large cities and a smaller group comes from harder to reach areas. The model may work well for the dominant group and often fail elsewhere. I would show case counts and mistakes for relevant slices before accepting a single overall percentage.
Avoid splitting the data indefinitely in search of a dramatic result. In a tiny group, one parcel can change an error rate substantially. Define useful slices from the process, such as region, carrier or service type, then show their counts. One mistake out of two observations calls for different caution from a similar percentage over a thousand cases. The numbers need their context.
For unusual cases, return to the inputs. Did a fresh scan fail to arrive? Was a category unfamiliar? Was the promised deadline different? Each explanation points towards a different improvement. Replacing the algorithm may not help if the real issue is a label definition or missing information that a warehouse employee could see but the model could not access at the decision time.
Leave an understandable experiment record
For each version, record the data period, label definition, inputs and evaluation rule. Add the environment version and explain what changed since the previous attempt. This makes it possible to distinguish a methodological improvement from a different period, removed hard cases or a preparation error. Those explanations can produce very similar looking changes on the final performance chart.
A learning project does not need a large experiment platform immediately. It needs enough clarity for someone else to reconstruct the comparison. A short project note can be sufficient for practice. In a team, use the existing documentation approach. I would focus on being able to explain where every number shown to the reader came from and what conditions it depends on.
Close the stage with a recommendation: the proposed option, its limitations and the next question to resolve. If two methods offer similar usefulness, discuss maintenance cost, input availability and diagnosis. This is where modelling connects with responsibility for a solution. A ranking of scores cannot make that wider decision for the team without understanding the process in which the model will operate.
How I would present a learning project
Start with a short problem description and a synthetic table. Show the prediction time, label definition and three permitted features. Add a field you deliberately reject because it is created only after delivery. That exercise demonstrates an understanding of limits before you build a sophisticated model or a finished application. You can explain every choice using a small number of cases.
Then prepare a simple baseline and a hand-worked mistake summary. Explain what the reader could do with the output. Add a reason to stop the project or request better data. Recognising that the material cannot yet support a reliable assessment is part of technical independence. A project does not need to claim success at every stage to demonstrate useful analytical judgement.
If you are starting out, first practise a small analytical project and data quality checks. Increase complexity afterwards. I want to see a project whose author understands the question, the records and the model’s mistakes. That creates a much more interesting discussion than another score with its conditions left unexplained.
Key takeaways
Is data science only about predicting the future?
No. It can also involve exploration, experiments, describing relationships and evaluating solutions. Predictive models are one possible tool, and responsibilities vary between teams.
How is a data scientist different from a data analyst?
Building and evaluating statistical or machine learning models is more common in data scientist roles. Both roles involve data, questions and communication. Actual responsibilities matter more than the title.
Does high accuracy mean a model is useful?
Compare it with a baseline, class frequencies and the costs of errors. Always predicting an on-time delivery can achieve high accuracy when delays are rare while detecting none of the problems.
AI was used in an automated way while working on this article. If you want to learn how to do it too, check out this project.
