
KajoData / SQL
SQL formatting: readable code and verified results
I separate SQL style preferences from calculation changes. Use a small dataset to check aliases, joins, filters and safe refactoring.
You open a query written a month ago. You remember that it worked, but not why a condition sits in that particular place. Names such as a, b and temp2 offer little help. Reading the code starts to feel like solving a crime. I enjoy a mystery, but in a report I would rather establish quickly what was calculated.
Good SQL style helps readers recover the author’s intention and notice a risky edit. Indentation, aliases and comments should serve that purpose. There is no mandatory comma arrangement that turns every query into good code. Some changes that look cosmetic also change the answer, and those deserve much closer attention than personal formatting preferences.
I use a complete synthetic example in SQLite below. First we will change the layout without changing the meaning. Then we will change a join and get a different answer. That separates an editorial preference from a calculation rule. Run the blocks in sequence in one empty test connection.
Agree on conventions before defending preferences
I prefer descriptive names, consistent indentation and visible clause boundaries. Keyword capitalization is a style choice. I use uppercase here because it makes the structure easy to spot. In an existing project, I would follow the agreed convention instead of changing hundreds of lines merely to make the code look familiar to me.
Consistency matters when reviewing changes. If one patch introduces a new condition and reformats the entire file, the actual calculation change becomes harder to find. I usually separate those steps. First I organize the layout and verify that the results agree. Then I change the reporting rule and explain the difference I expect.
A team can start by agreeing on indentation, aliases, commas and naming. The convention should work for real code, including long expressions and several joins. If a rule makes a particular section harder to understand, I prefer a justified exception over a competition to keep every column perfectly aligned in the editor.
Data for comparing two layouts
We have three customers and three orders. Ada placed two orders, Ben placed one, and Celina placed none. A customers row represents a customer; an orders row represents an order. That difference determines how many rows a join can produce. Even immaculate formatting cannot substitute for understanding it.
-- example: fixture
CREATE TEMP TABLE customers (
    customer_id INTEGER PRIMARY KEY,
    customer_name TEXT
);
CREATE TEMP TABLE orders (
    order_id INTEGER PRIMARY KEY,
    customer_id INTEGER,
    status TEXT,
    amount INTEGER
);
INSERT INTO customers VALUES (1, 'Ada'), (2, 'Ben'), (3, 'Celina');
INSERT INTO orders VALUES
    (101, 1, 'paid', 100),
    (102, 1, 'cancelled', 50),
    (103, 2, 'paid', 80);
Amounts are arbitrary points, not real sales. I want to count paid orders for every customer, including people who have not bought anything. I write that requirement before the query because Celina’s presence distinguishes two superficially similar reports. Without an explicit expectation, it is easy to accept either answer as correct.
Notice Ada’s cancelled order too. It lets us check where the status filter operates. A sample containing only paid purchases might hide a misplaced condition. I choose small test datasets to expose differences between possible interpretations. A neat sample where everything matches is pleasant to read but often weak at detecting mistakes.
Change the layout while preserving the answer
The first version is cramped, but it performs the same calculation as the second. Whitespace in these positions does not change columns, joins or conditions. I compare the results on the same data instead of assuming equivalence merely because the editor calls an operation formatting. An accidental edit can still happen during a cosmetic change.
-- example: compact
SELECT c.customer_id,c.customer_name,COUNT(o.order_id) AS paid_orders FROM customers AS c LEFT JOIN orders AS o ON o.customer_id=c.customer_id AND o.status='paid' GROUP BY c.customer_id,c.customer_name ORDER BY c.customer_id;
-- example: formatted
SELECT
c.customer_id,
c.customer_name,
COUNT(o.order_id) AS paid_orders
FROM customers AS c
LEFT JOIN orders AS o
ON o.customer_id = c.customer_id
AND o.status = 'paid'
GROUP BY
c.customer_id,
c.customer_name
ORDER BY c.customer_id;| customer_id | customer_name | paid_orders |
|---|---|---|
| 1 | Ada | 1 |
| 2 | Ben | 1 |
| 3 | Celina | 0 |
In the second version I can identify the source, join type and matching condition more quickly. I can also see that the query counts order identifiers. COUNT(*) would count the retained row for Celina even though no order matched it. That is a calculation issue. Good layout helps expose it, but cannot choose the correct function for you.
Names should explain what the result means
The alias paid_orders says more than cnt or value. It may need further detail if the report distinguishes placed, paid and shipped orders. I try to name the feature that separates a measure from its neighboring columns. The name does not need to reproduce the entire specification, but it should not hide an important restriction either.
I use snake_case because it is convenient to type and reuse. Spaces can be legal in appropriately quoted identifiers, so I would not describe them as a language error. They simply make everyday work less convenient and increase dependence on the quoting rules of particular tools. Friendly display labels can be assigned later in the presentation layer.
I also avoid giving different measures the same name. If revenue sometimes means before returns and sometimes after returns, consistent indentation will not resolve that ambiguity. Document the scope and units in the model. Code is part of communication, but it should not be the only place where an important business definition survives.
Aliases show where columns come from
In a join, c.customer_id and o.customer_id distinguish identically named columns. These aliases are short but visibly connected to their tables. If several sources were similar, I would choose longer names such as current_orders and archived_orders instead of making the reader remember which letter represents which version of the data.
Qualifying columns is not required in a simple single-table query. It is not a mistake either. It can make later extensions easier or follow an existing project convention. The earlier version of this guide presented that choice too categorically. I now treat it as a contextual readability decision rather than a universal prohibition.
Pay particular attention when the same name appears on both sides of a condition. Does customer_id = customer_id compare two sources or a column with itself? Explicit aliases make the intention visible. When the engine reports an ambiguous column, identifying its source is part of fixing the problem, not merely a decorative improvement to the query.
JOIN and LEFT JOIN answer different questions
In an ordinary join, writing JOIN means an inner join. Adding the word INNER can make that intention explicit. Replacing it with LEFT JOIN changes what happens to unmatched rows. That replacement is not a universal style improvement. Our report must retain Celina, so I choose a left join deliberately.
-- example: inner
SELECT c.customer_id, COUNT(o.order_id) AS paid_orders
FROM customers AS c
INNER JOIN orders AS o
    ON o.customer_id = c.customer_id
    AND o.status = 'paid'
GROUP BY c.customer_id
ORDER BY c.customer_id;
This version returns only (1, 1) and (2, 1). It correctly answers a question about customers with matching paid orders. If the recipient expected all customers, it is incomplete. The database does not know the recipient’s intention and will not produce an error just because the query answers the wrong business question.
The source order in a left join matters too. Unmatched rows from the left side are retained, so the table after FROM should reflect the report’s population. Are you starting from all customers, all orders or only returns? I establish that before spending time deciding which side of a line should contain the comma.
Moving a condition can change the join
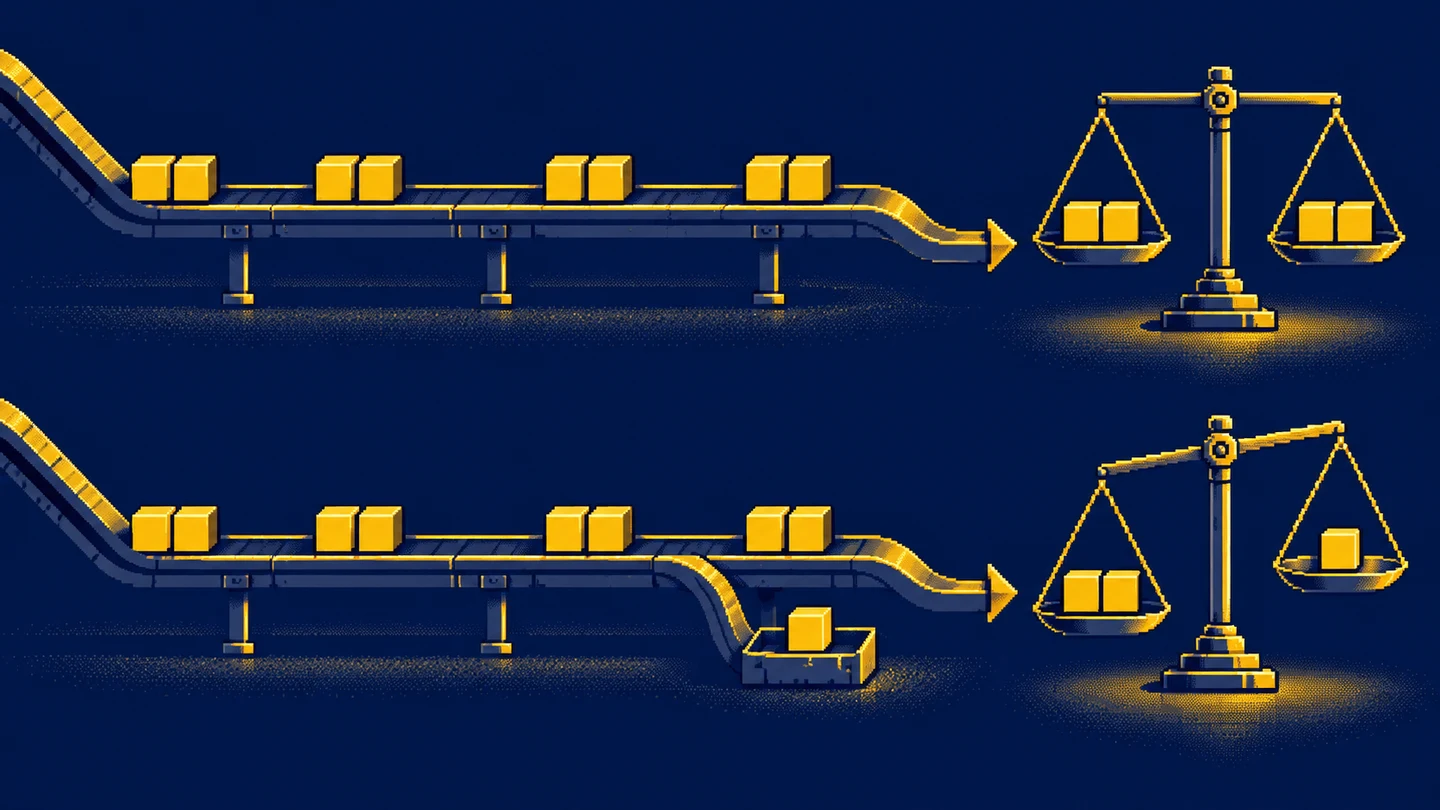
In the intended report, payment status belongs to the matching condition. A customer without a matching purchase is retained with missing order fields. Moving that restriction into WHERE makes the missing status fail the comparison and removes that customer. Better indentation cannot undo the semantic difference introduced by the move.
-- example: where-filter
SELECT c.customer_id, COUNT(o.order_id) AS paid_orders
FROM customers AS c
LEFT JOIN orders AS o
    ON o.customer_id = c.customer_id
WHERE o.status = 'paid'
GROUP BY c.customer_id
ORDER BY c.customer_id;
Again, only customers 1 and 2 remain. This is why a review should include a customer without any match and a customer whose only orders are cancelled. The second situation is absent from the starting sample, but it is worth adding during testing. Both customers should remain in a report whose population is all customers.
You can check the join and filtering rules in the SQLite SELECT documentation. When organizing existing code, I do not move conditions between ON and WHERE without a separate assessment. I describe that as a calculation change, including the expected difference and a concrete example that makes the difference visible.
Quotes, inequality and small conventions
I write text literals in single quotes, as in 'paid'. Identifier quoting depends on the dialect and settings. I avoid making a portable example depend on an engine accepting double quotes as string delimiters. A tolerated extension can stop working after a settings change or a move to another database.
The inequality operator <> is valid SQL. SQLite also supports !=. There is no reason to label the first spelling incorrect or promise a performance advantage for the second. I follow the project convention and remember that neither replaces IS NULL when testing missing values. The expression documentation explains the relevant engine behavior.
Commas can appear at the end of a line or before the next item. What matters is that the list remains readable and easy to edit. I use trailing commas in this guide, but I would not reformat an entire repository while fixing one filter. The extra review effort can outweigh the benefit of satisfying a personal preference.
Comments explain decisions and exceptions
A comment saying “select the identifier” above SELECT customer_id adds little. Explaining why cancelled orders are excluded or why customers without purchases remain is more helpful. Those intentions are not always recoverable from syntax alone. A good comment anticipates a real question that a future reader may need to answer.
A -- comment ends at the end of its line; a /* ... */ comment has an explicit closing marker. Both forms are valid in SQLite. A tool that joins lines without understanding comments can damage a query. That is a text-processing problem to investigate in the tool, not proof that line comments are inherently wrong.
Comments age too. When changing a condition, I check its explanation so that the file does not retain contradictory versions of the rule. I avoid large blocks of old commented-out SQL when version history already preserves them. The current file should make the current calculation and its reasoning easy to identify.
CTEs organize stages without promising speed
A named stage can be easier to understand than several nested subqueries. A common table expression lets you separate preparation from the final report. I choose stage boundaries according to meaning rather than line count. Three names describing real transformations help more than ten labels such as step1, step2 and final_final.
I do not assume that a CTE will always run faster than a subquery. Execution depends on the engine, version, plan and actual statement. SQLite documents CTE materialization as part of planner behavior, not a guarantee created by writing WITH. Performance claims need measurements of the relevant workload, not a preference for one visual structure.
During refactoring, I also check what one row represents between stages. A stage returning one row per customer can multiply those rows again when joined to orders. A descriptive name and a note about granularity help reveal that transition. The CTE tutorial develops a complete example of naming and checking calculation stages.
Explicit columns make later edits easier
The example groups by named columns instead of GROUP BY 1, 2. Positional grouping is available in some dialects, but ties the calculation to the order of the selected expressions. Moving a column may change the grouping or produce an error. Explicit names let a reviewer assess the change without tracking position numbers.
I treat ordering similarly. Is the output order part of the report’s requirements? Sorting only by order count leaves Ada and Ben tied. If the same data should produce a repeatable arrangement, add an identifier to break the tie. Formatting should make both criteria visible so that the second one does not disappear inside a long line.
Column aliases can be part of an interface too. Renaming paid_orders to orders_count might be harmless to a human while breaking a program that reads the result by field name. Reordering fields may affect a consumer that reads them by position. Refactoring therefore includes the contract with downstream consumers, not merely equality of the visible numbers.
Not every rename needs an elaborate process. Experiment freely in an isolated exercise. In an existing report, first establish who consumes the result and how they read it. When documenting a team convention, include that concrete example: a column heading used by another process explains the practical reason for caution better than a vague instruction to use good names.
A formatter still needs a review
An automatic formatter saves manual indentation work. Before using one, I choose the right dialect and check whether it understands the project’s syntax. SQL embedded in templates may contain additional constructs that a plain SQL formatter does not recognize. I start with a small section and inspect the resulting difference.
After formatting, I read the diff. Moving whitespace is different from removing a parenthesis, comment or quote. If the tool changed more than the expected layout, I stop and investigate. I do not accept an automatic edit simply because the new version looks more professional in the editor. Appearance is weak evidence of equivalent behavior.
Store a shared configuration in the project when several people need consistent output. A single learning exercise does not require an elaborate tooling system, however. Start with a stable layout, descriptive names and the ability to compare results. The tool should support those habits instead of adding another ritual with no visible benefit.
Check the change before handing it over
I first compare column names and order, then row counts and values. If row order matters, I make it explicit. If it is outside the report’s contract, I compare contents while retaining the number of repeated rows. Comparing plain sets can hide accidental multiplication of otherwise identical records.
I also check boundaries: no orders, unmatched customers, several orders for one customer and missing values. Passing a sample test does not prove equivalence for every possible dataset, but deliberately chosen cases expose common mistakes. That gives the reviewer concrete evidence beyond an assurance that the patch is “just formatting” and therefore does not need attention.
For an exercise, add a fourth customer with one cancelled order. Compare the three query variants. formatted should retain that customer with zero; inner and where-filter should omit them. Then reformat the intended report using your own convention and verify that its answer stays the same. Keep the calculation change separate from the layout experiment.
The historical SQL Format example archive remains available as material from the earlier article. It uses the original database and older conventions; it is not the executable dataset for this tutorial. Use the complete examples above for the current exercise. If you are just starting out, begin with SELECT and filtering.
Key takeaways
Can SQL formatting change the result?
Whitespace changes in appropriate positions preserve the calculation. Changing a join, condition placement or expression may change the answer and needs separate verification.
Is LEFT JOIN better style than INNER JOIN?
The question determines the join type. LEFT JOIN retains unmatched left-side rows, while INNER JOIN requires a match. Replacing one with the other is not cosmetic.
Does a CTE always make a query faster?
There is no such guarantee. CTEs help name stages, while performance depends on the engine, version, data and execution plan.
